
I. INTRODUCTION
An outbreak of Severe Acute Respiratory Syndrome Coronavirus 2 (SARS-CoV-2) which was first reported in Wuhan, China in December 2019 [1], [2], has led to 3, 910, 738 confirmed cases, 272, 778 death cases, with 2, 352, 811 active cases, and 1, 306, 204 recovered cases as of May 8, 2020, and has spread to 215 countries of the world, [3], [16], [17], [18]. Coronaviruses are a large family of viruses that may cause respiratory illnesses in humans, ranging from common colds to more severe conditions such as Severe Acute Respiratory Syndrome (SARS) and Middle Eastern Respiratory Syndrome (MERS). People that are infected may be sick with the virus for 1 to 14 days before developing any symptoms, [19], [20]. The most common symptoms of coronavirus disease (COVID-19) are fever, tiredness, dry cough, and in severe cases difficulty in breathing [28]. From the statistics given above, it suggests that about of the people infected with the virus will recover from the disease without going through special treatment.
Thus, "Novel Coronavirus" is a new, previously unidentified strain of Coronavirus. This novel coronavirus that is involved in the current outbreak has been named Severe Acute Respiratory Syndrome Coronavirus-2 (SARS-CoV-2) by the International Committee on Taxonomy of Viruses on 11 February, 2020 [28]. While the disease it causes has been named "Coronavirus Disease 2019" (or "COVID-19" in short) by World Health Organization (WHO) [29]. As a world, we now have a critical situation on our hands with the spread of pandemic COVID-19 which has posed a huge threat to global public health. Economic of the world is also suffering greatly as a result of several measures been put in place including total lock-down of cities in order to curb the spread of the disease. It has also had social, environmental and financial consequences, [18], [21], [22], [23], [30].
Understanding the early transmission dynamics of infectious diseases and evaluating the effectiveness of control measures is crucial for assessing the potential for sustained control when occurring in new areas. Preliminary investigation has suggested that the key influencing factor for the rise in cases across the globe is the disease spread by the infectious people. This means that those with the virus can unknowingly infect others before symptoms appear, some as soon as two days after infection. It is assumed that infected individuals are able to spread the infection until they recover, [24], [25], [26]. As a consequence, several measures have been put in place by the governments and health authorities in order to reduce the spread among the populace. There has been a regular campaign to encourage taking personal measures that will help in reducing the spread. These are the practicing of regular hands-washing, observing social distancing, the use of face masks, disinfection, isolation, among others, [27].
As a new infectious disease, the transmission dynamics of COVID-19 is still under investigation. Al- though SARS-CoV-2 is a kind of coronavirus that is similar to Severe Acute Respiratory Syndrome Coron- avirus (SARS-CoV) and the Middle Eastern Respiratory Syndrome Coronavirus (MERS-CoV), many studies are still underway to understand its infectious characteristics.
Since the outbreak of the disease, several study have been made by researchers to understand the COVID-19 disease, to model and to predict the spread with the help of scientific tools such as mathematical models, predictive analytics using machine learning algorithms, and time series forecasting.
In [9], the author presented a comprehensive understanding of various pathological mechanism of COVID-19, which can potentially influence the vulnerable development of the disease. In [10], the author build SARS-CoV-2 computed tomography (CT) scan dataset, consisting of 2482 CT scans for both infected and non-infected patients of SARS-CoV-2 (COVID-19). The data which was collected from Sao Paulo in Brazil is publicly available online to encourage research and implementation of artificial intelligent methods, able to identify an individual infected by COVID-19 through analysis of patient's CT scan. In [11], the authors designed a 3-dimensional structure for 2019-nCoV. To elucidate the 3D structure, a computational modeling approach was applied to give insight into the domain architecture of nsp12. In [12] the authors reviewed the characteristics, origin, pathogenicity, genome structure, and replication of SARS-CoV-2, with the goal of explaining how each remedy strategy could act on slowing down or preventing viral infection. Summary of recently investigated treatments (drugs) were presented. In [13], the authors evaluated the safety and efficacy of 2 chloroquine diphosphate (CQ) dosages in patients with critical SARS-CoV-2. The preliminary findings in this study suggest that higher CQ dosage should not be recommended for patients with critical case of the viral infection because of its potential safety hazards. In [14], a set of novel molecular structures of SARS-CoV-2 3C-like protease inhibitors were presented using the Insilico medicine generative chemistry pipeline. 10 representative structures for likely development with 3D representation were presented. [15] in their work, using the data provided by [6], describes the timeline of a live forecasting exercise, and provides objective forecasts for the confirmed cases of COVID- 19. They discussed also in their work that forecasting of COVID-19 has good potential implications for planning and decision making.
Motivated by [5], [26], [15], the goal of this paper is to study and understand the early-stage evolution of the disease spread with a data-driven approach using Mathematical SIR model and Machine Learning regression model for time series forecasting of the COVID-19 disease, with and without lags and trends.
The rest of the paper is structured as follow: the formulation and application of SIR model to COVID-19 are presented in section II, Data analysis and Time series forecast in section III and section IV give the conclusion to this work.
II. THE SIR MODEL
In this section, we formulate and analyze SIR mathematical model which is the most basic mathematical model for a directly transmitted infectious disease as COVID-19 which is caused by a virus. The transmission of the disease occurs through respiratory droplets, and spread by individual-to-individual contact which happens through a sneeze or cough, through skin-skin contact, or through indirect contact with surfaces in the immediate environment or with objects used on the infected person [4].
a) Mathematical Formulation of SIR Model
The model partitioned the total human population at a particular time into three sub-populations to explains the transmission of the disease in the human population. The total human population which we denoted , is divided into sub-populations of Susceptible class , Infective compartment and Recovered/Removed class . So that the total population, is given as:
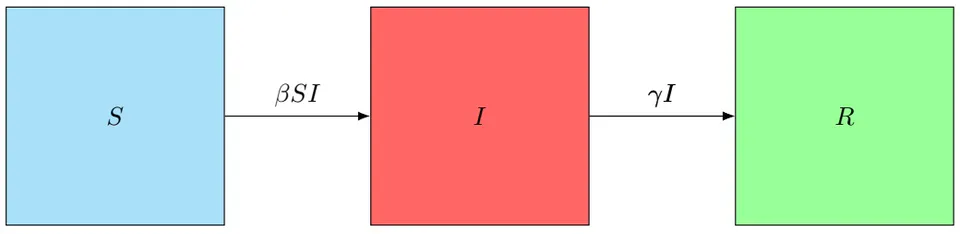
Susceptible class represent individuals who are at risk of contracting the infection if they had contact with infected individuals. Infective compartment consists of individuals that may not or showing the symptoms of the disease and can infect others. The recovered/removed human compartment are the individuals who have recovered or diseased from the disease. Figure 1 shows flow diagram of COVID-19 disease in a deterministic population. The model variables and their meaning are presented in table I.
| Variable | Meaning |
| S(t) | The number of susceptible individuals at a given time, t |
| I(t) | The number of infective individuals at a given time, t |
| R(t) | The number of recovered individuals at a given time, t |
The SIR COVID-19 disease transmission model is formulated by assuming the following assumptions as used in [5].
- There is a large and homogeneously mixing population.
- The outbreak of the disease is short lived.
- The model assumed that there is no natural births or natural deaths that occur.
- The infection has zero latent period. This means that an individual can spread the disease as soon as they become infected with the disease.
- Recovering from infection may not necessary confers lifetime immunity since there is no vaccine yet to cure the disease.
- There is an assumption of the mass-action mixing of individuals. By mass action mixing it is assumes that the rate of an encounter between Susceptible and Infective individuals is directly proportional to the product of the population sizes. By this we mean, doubling the size of either Susceptible or Infective population will result in twice as many new infection cases per unit time. This requires that the individuals of both populations are homogeneously distributed in space and thus do mix either in any smaller subgroups or larger. Understandably, every individual will encounter every other individual per unit time with equal probability. Readers should, however, keep it in mind that the SIR model is a deterministic model and there are no probabilities assumptions involved in the formulation of the model.
In the formulation of the model, we do not consider the effect of the natural death or birth rate. This is because the model assumes the effective period of the disease is much shorter than the lifetime of the human. The model lets us know the importance of knowing two parameters, namely and . We will consider also that people develop immunity (in the long term, immunity may be lost and the COVID-19 may come back within a certain seasonality such as also find in the case of common flu disease), and there is no transition from recovered to the remaining two classes.
With the model flow diagram and assumptions above, the differential equations that governed the system are now given below:
Where is the contagion rate of the disease and is the recovery rate. The disease transmission rate is >0 and the recovery rate is >0 also (that is, the duration of infection denoted D is equal ). The incidence term for the number of new infected individuals per unit time corresponds to homogeneous mixing of the infected and susceptible sub-populations.
It can be easily verified that , and is therefore constant. That is, the total population is constant. This easily follows from the SIR system above that the sum of the left hand sides of the three equations is the derivative of the total population size and the sum of the right hand sides is zero. Where the total population size is denoted by . Since , the system can thus be reduced to a system of two ODEs namely (2) and (3).
Now, Suppose that each infective individual has contacts that will potentially be from the susceptible class and provided that each infective individual is capable of transmitting the disease per unit time, where is independent of the population size, then, of these contacts are with other susceptible individuals. If the fraction, denoted , of adequate contacts result in transmission of the disease, then it follows that each infected individual infects susceptible individuals per unit time. Thus, we have that , where . The parameter is called the transmissibility of the COVID-19 disease.
b) Analysis of the SIR Model
- The Long Term Limits Existence: We show that the long term limits of the SIR model exist.
Now, since the right hand side of (2) is negative and the right hand side of (4) is positive, this implies that and .
Also, since and , this implies that the limits , , and thus exist.
- The Disease Always Dies Out: It is also easy to prove that the disease always dies out. Now, for all initial conditions, without formulating a formula for . Suppose now that the disease will not die out, (4) implies that for sufficiently large , and this implies that , this is a contradiction. Hence, the disease will die out.
- Theorem of Epidemic Threshold: We define the effective reproductive number, which we denoted and the basic reproduction number denoted, .
Now, if the entire population is initially susceptible, with one infective case, that is, , , and large (see the model assumptions), then is approximately equal to . Hence, to modify formula involving , we shall assume that the quantity is equal to 1. We now show that is the threshold parameter that determines whether the infectious disease will quickly die out or whether it will permeate the population and cause an epidemic.
Theorem 1.
- If , then decreases monotonically to zero as
- If , then starts increasing, reaches its maximum, and then decreases to zero as . The scenario of increasing numbers of infected individuals is called an epidemic. It follows that an infectious disease can get into a population and cause an epidemic in an entirely susceptible population if or .
Proof.
Equation (3) and the discussion in Section 2.2.1 imply that for . This observation together with (see Section 2.2.2) proves the first statement.
Equation (3) implies for . Thus is increasing at . Equation (3) also implies that has only one non-zero critical point. These observations, together with imply the second statement is true. This end the proof.
c) Existence and Uniqueness of Solution for the SIR Model
The first-order ODE is generally in the form:
In order to established the existence and uniqueness of solution of (5), we are interested in answering the following questions:
- (I) Under what conditions can we say solution to equation (5) exists?
- (II)Under what conditions can we say there is a unique solution to equation (5)?
In order to answers these questions:
Let:
and
We use the following theorem to established the existence and uniqueness of solution for our SIR model.
Theorem 2 (Uniqueness of Solution)
Let denotes the domain:
and suppose that satisfies the Lipschitz condition:
and whenever the pairs and belong to the domain , where represents a positive constant.
Then, there exists a constantsuch that for any initial condition in the interval, there exists a unique (exactly one) continuous vector solutionof the system(5). It is important to note that condition(2.12)is satisfied by requirement that:
be continuous and bounded in the domain .
Lemma 1: has continuous partial derivative on a of real bounded closed convex domen (i.e., convex set of real numbers) where is used to denote real numbers, then it satisfies a Lipschitz condition in . Our interest is in the domain:
So, we look for a bounded solution of the form
We now prove the following existence theorem.
Theorem 3: (Existence of Solution)
Let denote the domain defined in (6) such that (7) and (8) hold. Then there exist a solution of model system of equations (2)-(4) which is bounded in the domain .
Proof. Let:
and
We shows that:
are continuous and bounded. That is, the partial derivatives are continuous and bounded. We explored the following partial derivatives for all the model equations:
From equation (9);
Similarly, from equation (10) we also have that:
Finally we have from equation (11);
We have clearly established that all these partial derivatives are continuous and bounded, hence, by Theorem (1), we can say that there exist a unique solution of (9) to (11) in the region D.
d) Implementing the SIR Model Numerically
The SIR model can be implemented in many ways. It can be implemented from the differential equations governing the system, that is within a mean-field approximation. Also, it can be implemented running the system dynamics in a social network (i.e. graph). We will choose the first option and will run a numerical method (with 4th order Runge-Kutta method) to solve the differential equations system.
We define the functions governing the differential equations (2)-(4) using the python programming language. The functions are given below: "
{"code_caption":[],"code_content":[{"type":"text","content":"# Susceptible equation\ndef fa(N, a, b, beta):\nfa = -betaab\nreturn fa\n\n# Infected equation\ndef fb(N, a, b, beta, gamma):\nfb = betaab - gammab\nreturn fb\n\n# Recovered/Deceased equation\ndef fc(N, b, gamma):\nfc = gammab\nreturn fc"}],"code_footnote":[],"code_language":"python"} Where , and .
In order to solve the differential equations system, we develop a 4th order Runge-Kutta (RK4) numerical method using python programming language. Details of RK4 are discussed in [7].
The results obtained for world population, with one initial infected case (that is ), , and a time step are shown in the figure 2.
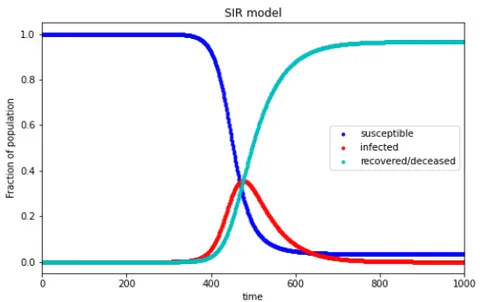
From the simulation result depicted in the figure 2, the following observations was made:
- The number of infected cases increases for a certain period of time, and then eventually decreases, given that individuals will recovered/deceased from the disease.
- The susceptible compartment of the population decreases as the virus is transmitted and eventually drop to the absorbent state 0
- However for the recovered/deceased case, the opposite happens.
Readers should however, note that different initial conditions and parameter values will lead to other scenarios from the simulation.
- Fitting the SIR model to the Real Data: Since the beginning of the COVID-19 pandemic, efforts have been put in place to collate live updates of the disease across the globe. For the purpose of our analysis in this paper we are using the data provided by the Center for Systems Science and Engineering (CSSE) at Johns Hopkins University [6] which provide daily updates on the COVID-19 cases that are curated from different official sources.
The SIR model we modeled relied heavily on theoretical assumptions, and we are interested into real approximation of the COVID-19 expansion in order to extract insights and understand the transmission of the virus. Hence, there is need for us to extrapolate the values of and parameters for each case if we hope to be able to predict the evolution of the system.
We considered selected country of interest and fitted the model with the real COVID-19 data of the country and observed how the evolution of the system looks like with the optimal parameters values of and for the country. See figure 3 below.
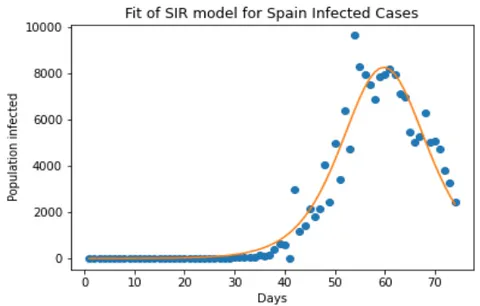
The optimal parameters extrapolated for the model fit in the figure 3 above are and . The yellow line indicates the SIR model while the blue dots represent the data points.
III. DATA ANALYSIS AND TIME SERIES FORECASTING OF COVID-19 DATA
Analyzing the SIR model and the simulations given in the section 2 was meant to understand a model that approximately resembles the transmission mechanism of the COVID-19 virus. However, there are alternative methods that prove to be equally useful both to predict and to understand the pandemic evolution, namely machine learning methods. Many of the popular machine learning methods rely on having rich data to extract conclusions and allow algorithms to extrapolate patterns in data. On the COVID-19 data, we will be considering the machine learning regressions approach under this section.
The COVID-19 dataset we used in the analysis includes dates from January 22 to April 14, 2020, totalling 84 days. This dataset covers 184 countries affected by the disease. Countries with Province/State informed are Australia, Canada, China, Denmark, France, Netherlands, the US, and the United Kingdom. Since the data is close to 3 full months from 2020, this is enough data to get some clues about the pandemic. We give the description of the dataset in Table II below:
| Feature | Description | Type |
| Id | Unique ID | Integer |
| Province_State | Province/State in Country/Region | Character |
| Country_Region | Country/Region with COVID-19 Cases | Character |
| Date | Date of case reported | string |
| ConfirmedCases | Number of Confirmed Cases | float |
| Fatalities | Number of Fatalities Cases | float |
We performed some preprocessing to prepare the dataset for training. This consist of filtering of dates to remove Confirmed Cases and Fatalities post-March 12, 2020 for the short term forecasting purpose, we created additional date columns, analyzed and fixed missing values from the data, and also did data transformations.
Understanding the evolution of the disease spread is vital for the early forecast, so we plot some visuals to understand the evolution of the disease.
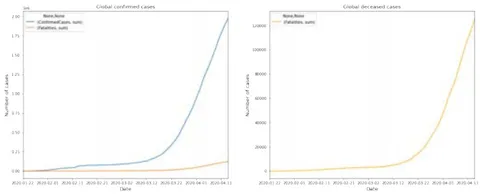
Figure 4 show the global COVID-19 curve. It shows a rich fine structure, but these numbers are strongly affected by the vector zero country-China. We called China vector zero country due to the fact that the COVID-19 disease pandemic started there. Now, during the initial expansion of the virus in China, there was no reliable information about the real infected cases. In fact, the criteria that was used to consider as 'infectious cases' in the COVID-19 dataset was modified around February 11, 2020. This strongly perturbed the curve, this is evidence as can seen in the figure 4.
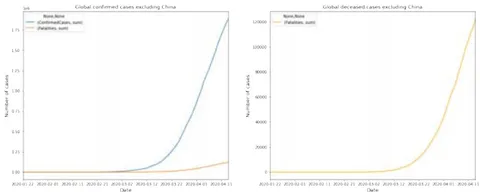
It was observed in figure 5 that the global COVID-19 general behaviour looks cleaner, and in fact, the curve resembles a typical epidemiology model like SIR. We recalled that the SIR mathematical model presents a large increase in the number of infections cases that, once the infectious cases reaches the maximum of the contagion, will then decrease with a lower slope.
a) Linear Regression Versus Log-Linear Regression Models
Since we are interested in predicting the future time evolution of the pandemic, our first approach in the paper was to use Machine Learning Linear Regression model for the prediction of the earlier spread of the disease. However, we realized that the evolution is not linear but exponential (this has been discovered from the beginning of the disease spread) so that a preliminary log transformation will be required on the data in order to trained linear model.
The figure 6 below shows a visual comparison of both Confirmed Cases and log Confirmed Cases cases for Spain and with the data information from the last 10 days, beginning from March 1, 2020:
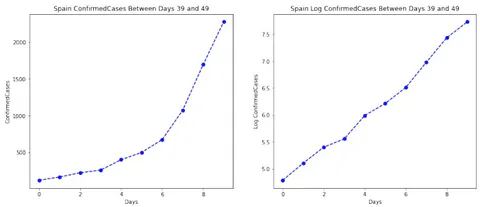
As can be seen in figure 6, the log transformation results in a fancy straight-like line, which is impressive for Linear Regression. However, some important points need to be clarified. This "roughly exponential behaviour" of the curve is only true for the initial disease spread of the COVID-19 pandemic (that is the initial increase of infections on the SIR model). But that is exactly the point where most countries are at as at the time of writing this paper. In our analysis, we only extract the last 10 days of data in order to capture exactly the very short term component of the evolution to prevent the effects of certain variables that have been impacting the transmission speed, for instance, the effect of quarantine in comparison to when there is free circulation, etc, and also to prevent differences on criteria when confirming new cases.
We follow the steps below in training the linear regression model:
- Features Selection. We select features for the training.
- Dates filtering. We filtered the train data from March 1 to March 18, 2020.
- Application of Log transformation. We applied log transformation to Confirmed Cases and Fatalities features.
- Handled infinities. We Replace infinities from the logarithm with 0 values. Given the asymptotic behaviour of the logarithm for , this implies that when applying the inverse transformation (exponential) a 1 will be returned instead of a 0. This problem does not impact many countries. In our subsequent work, we intend to address this issue in order to obtain a cleaner solution.
- train/test split. Split the data into train/validation/test sets
- Prediction. Apply Linear Regression, and trained the model country by country after which the results was joined together.
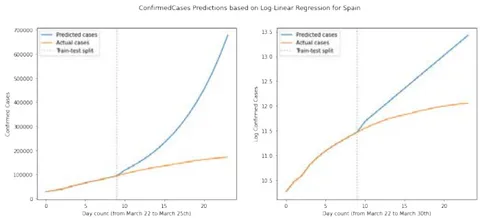
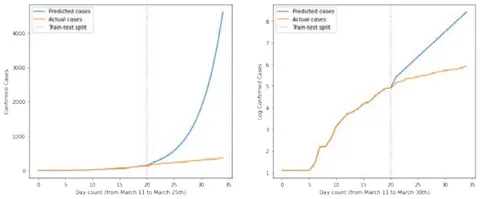
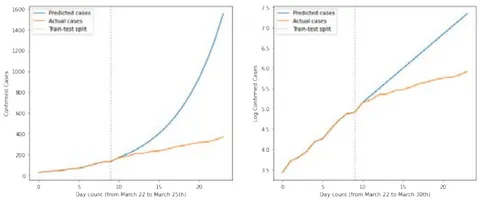
Figures 7 to 10 shows the results for some of the countries after training the model.
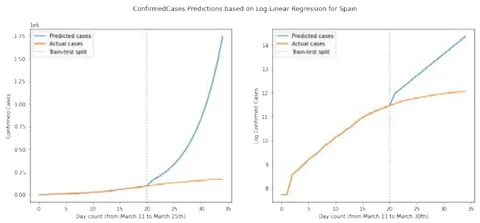
From the regression results, some of which were depicted in the figure 7 to 10, the following general observations were noticed:
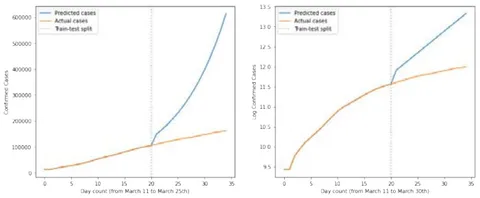
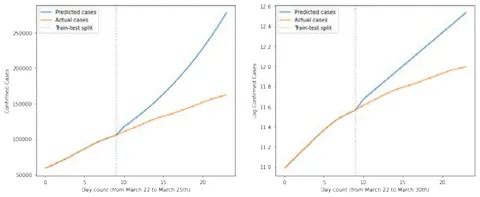
The general evolution of the disease spread is captured despite the simplicity of the model.
The cumulative infected cases have been changing since March, so that using the whole month data for training the model will result in overestimated predictions. When we reduced the training set to only a few days prior to the testing region, results are better. This is capturing the problem of the exponential behaviour that is only true for the early stages of the disease spread. The stage we are now, the disease spread behaviour is more complex, and in order to predict the evolution with large portions of the historic data, alternative and better models will be required (e.g sigmoid, ARIMA, etc.).
Estimations are increasingly worse as time passes (getting harder to extrapolate).
Countries that recently confirmed their first contagions are difficult to predict (i.e, countries with fewer data points)
Countries with 0 cases in the whole training dataset are predicted as non-infected (countries with no data points).
b) Linear regression with Lags and Trends
With the results obtained in the previous subsection, we can deduce that the Linear Regression Model is a good model for predicting the early stages of the COVID-19 spread. That is, Linear regression model can predict the initial outbreak of the disease from the data we are analyzing, and there's no way our model could predict when the number of new infections is going to decrease. But for short-term prediction purposes, everything is fine. We will now try to improve the results obtained previously in this subsection.
Time series data possess specific properties such as trend and structural break, common methods used to analyze other types of data may not be appropriate for the analysis of time series data [8]. So, enriching time series data is key to obtain good results, therefore, we applied two different transformations to the COVID-19 data in this subsection, namely lags and trends. For example, on Confirmed Cases column, lags can be seen as a way to compute the previous value of the column so that the for Confirmed Cases would inform this column from the previous day. By definition, the of a feature X is given by the formula:
Transforming a column into its trend gives the natural tendency of this column, which is different from the raw value. The definition of trend we applied is given by:
The backlog of Lags we will apply is 14 days while for Trends is 7 days both for Confirmed Cases and Fatalities.
In order to apply lags in the model, there is a problem to solve: If we use our dataset to predict the next following days of contagions, for the first day, all the lags will be reported (from the previous days), but for the next days, many of the lags will be unknown (and will be flagged as 0), since the number of Confirmed Cases is only known for the training subset. We take the following simple approach to overcome this problem:
(i) We begin with the train dataset, with all cases and lags reported
- (ii) We forecast only for the next day through the Linear Regression
- (iii) We set the new prediction as a Confirmed Cases and Fatalities
- (iv) We recompute lags
- (v) We then repeat from step (ii) to step (iv) for all the remaining days.
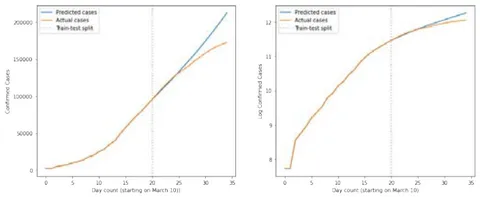
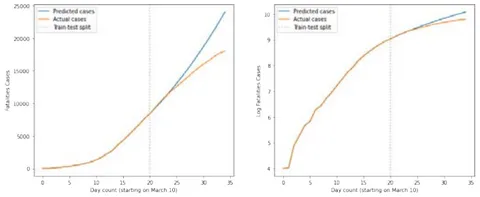
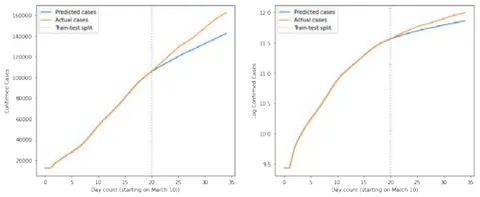
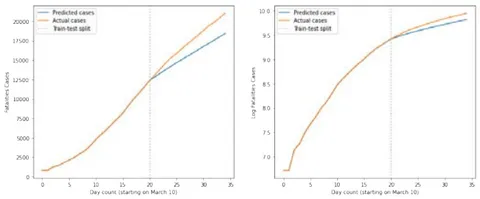
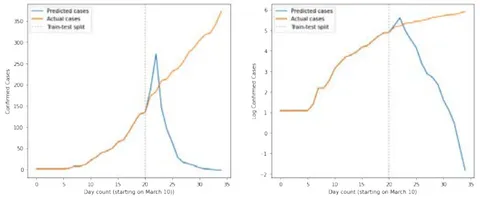
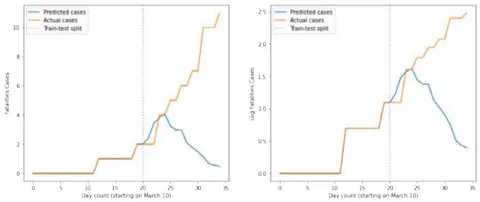
Figure 13 to 18 shows some of the regression results with the addition of lags. Two full weeks of the data was used for the training (from February 26th to March 11th), with their previous 14 lags. With the addition of the lags, the following observations were made:
Countries with enough data: For countries with several Confirmed Cases and Fatalities (For example, Spain, Italy) in the train dataset (prior to March 11th), predictions are very precise and similar to actual data points.
Countries with poor data: Countries with a small number of data points (e.g. Nigeria) in the train dataset show a potentially disastrous prediction. Given the small number of cases, the log transformation followed by a Linear Regression is not able to capture the future behavior of the disease spread.
Countries with no data: When the number of con- firmed cases in the train dataset is 0 or negligible, the model predicts always no infections.
IV. CONCLUSION
Understanding the evolution of the spread of a disease like COVID-19 will ultimately play a major role in prevention measure that can be taken by relevant authorities to flatten the curve. The aim of this paper was to explore and understand the early time evolution of the spread of COVID-19 disease with a data-driven approach. Therefore, we modelled and applied COVID-19 disease to the SIR epidemiological model. Also, we use the machine learning linear regression model on the COVID-19 data that is publicly available for early-stage time series forecasting of the COVID-19 cases, considering when there is no lags and trends, and with the application of lags and trends. With these approaches, we are able to capture and understand the early spread of the disease. Hence, we suggest that if using a more advanced deterministic epidemiological model, and sophisticated machine learning regression models on the COVID-19 data, it is possible to understand, as well as predict the long time evolution of the disease spread.
Declaration of Interests
The authors declare that they have no known competing financial interests or personal relationships that could have appeared to influence the work reported in this paper.
Funding Source
The authors declare that there is no funding received for the writing of this paper.