I. INTRODUCTION
With the advancement of web of things, different substantial scale continuous information preparing in view of ongoing sensor information are turning into the key of the development of EPC (epcglobal arrange) application at present. The scholarly community, the industry and even the administration establishment have as of now gave careful consideration to enormous information issues and created a distinct fascination.
In this manner, the examination of ongoing huge information has incredible application prospect and research esteem. Because of the continuous and the expansive size of information handling and different elements that ongoing enormous information requires make the review for constant huge information preparing testing, for the most part progressively, strength and extensive scale and so on.
Real time: Real-time processing of big data mainly focuses on electricity, energy, smart city, intelligent transportation, and intelligent medical fields. During the information processing it needs to be able to make quick decisions, and feedback relevant instructions to the sensing terminal input within a very short time delay. For instance, in Fire monitoring and rescue system, its processing center needs to be able to analyze and process the data collected by sensors in the site of the incident in a very short period, to make integrated decision by comprehensively considering site information such as the movement of persons and the site form and meantime to issue the corresponding instructions to the site sensing terminals, such as what extinguishing agent used for rescue, how to protect people's safety in the site of the incident and how to help the firemen to rescue. At the same time, the information gathered by sensing terminals and instruction information must arrive information gathering or processing terminal in real time and make relevant decisions. The loss caused by that decision-making information can't be conveyed Stability: In real time is also incalculable, so real-time processing of large data is particularly important. the areas covered by Real-time
Large-scale: As talked about above, continuous huge information preparing frameworks are frequently firmly identified with urban foundation and real national application, so its application is regularly a tremendous scale. For example, shrewd city astute transportation framework, once the biggest ongoing information examination and choice are made, it frequently goes for transportation basic leadership at a commonplace and city level or even a national level, and significantly affects the national life.
Thus, this paper highlights the big data processing architecture under the cloud computing platform. It presents a data storage solution on heterogeneous platforms in real-time big data processing system, constructs a calculation mode for big data processing and points out the general framework for real-time big data processing which provides the basis for the RTDP (Real-Time Data Processing). Section 2 in this paper gives an overview of big data; section 3 discusses the differences and challenges between big data and real-time big data; section 4 points out the current deficiencies of cloud computing technology; section 5 combine cloud computing technology with the feature of real time big data to architect the processing platform for real-time big data; section 6 gives a demo about how the RTDP system is used in smart grid system and finally summarize this article.
II. BIG DATA OVERVIEW
Big data itself is a relatively abstract concept, so far there is not a clear and uniform definition. Many scholars, organizational structure and research institutes gave out their own definition of big data . Currently the definition for large data is difficult to reach a full consensus, the paper references Academician Li Guojies definition for big data: in general sense, Big Data refers to a data collection that can be obtained within a tolerable time by using traditional IT technology, hardware and software tools for their perception, acquisition, management, processing and service . Real-time data is a big data that is generated in real time and requires real-time processing. Per the definition of Big Data, Big Data is characterized by volume, velocity and variety where traditional data processing methods and tools cannot be qualified. Volume means a very large amount of data, particularly in data storage and computation. By 2010 the global amount of information
Data processing requires faster speed, and in many areas data have been requested to carry out in real-time processing such as disaster prediction and rapid disaster rehabilitation under certain conditions need quickly quantify on the extent of the disaster, the regional scope impacted etc. Variety refers to the data that contains structured data table, semi-structured and unstructured text, video, images and other information, and the interaction between data is very frequent and widespread. It specifically includes diverse data sources, various data types, and a strong correlation between the data.
With the advancement of PC and system innovation, as well as intelligent frameworks, big data has become increasingly relevant in everyday life. In 2008, a Big Data issue was released by "Nature," highlighting the importance of big data in biology and the necessity to build biological big data systems to address complex biological data structure problems[25]. Paper[25]emphasized that new big data systems must accommodate various data structures, including unstructured data, have flexible operability, and ensure data reusability. Furthermore, Big Data plays a crucial role in defending national network digital security, maintaining social stability, and promoting sustainable economic and social development[26]. With the advancement of big data technology, Big Data also plays an important role in creating smart cities and has significant applications in urban planning, intelligent traffic management, public opinion monitoring, safety protection, and many other fields[27].
III. DIFFERENCE AND CHALLENGES BETWEEN BIG DATA AND REAL-TIME BIG DATA
Huge information is trademark by multi-source heterogeneous information, broadly circulated, dynamic development, and "information mode after the data"[28] [29]. Notwithstanding having every one of the qualities with huge information, constant enormous information has its own attributes. Contrasted and the huge information, with regards to information reconciliation ongoing enormous information has higher prerequisites in information procurement gadgets, information examination devices, information security, and different angles. The accompanying presents from information incorporation, information investigation, information security, information administration and benchmarking.
a) Data Collect
With the improvement of web of things and Cyber Physical System (CPS) , the ongoing of information handling requires ever more elevated. Under the enormous information condition, various sensors and portable terminals scatter in various information administration frame work which makes information accumulation itself an issue. In RTDP framework, its ongoing information accumulation confronted makes information mix confronting many difficulties.
i. Extensive heterogeneity
In huge information framework, the information created by versatile terminals, tablet PCs, UPS and different terminals is frequently put away in reserve, yet in RTDP framework it requires information synchronization which conveys huge difficulties to the remote system transmission. When managing handling heterogeneity, huge information framework can utilize NoSQL innovation and other new stockpiling techniques, for example, Hadoop HDFS. However, the constant requires low in this sort of capacity innovation, where the information is frequently put away once yet read commonly. However, this sort of capacity innovation is a long way from fulfilling the necessity of ongoing enormous information framework that requires information synchronization. Because of broad heterogeneity of enormous information, information transformation must be done amid information incorporations preparing, however conventional information distribution center has clearly deficient to address the issues of time and scale that huge information requires .
ii. Data quality protection
In the time of huge information, it is a marvel frequently creates the impression that valuable data is being submerged in a substantial number of futile data . The information nature of Big Data has two issues: how to oversee substantial scale information and how to wash it. Amid the cleaning procedure, if the cleaning granularity is too little, it is anything but difficult to sift through the valuable data; if the cleaning granularity is excessively coarse, it can't accomplish the genuine cleaning impact. So, between the amount and quality it requires cautious thought and measured which is more apparent progressively enormous information framework. From one perspective, it obliges framework to synchronize information in a brief span; then again, it additionally requires the framework to make a fast reaction to information progressively. The execution necessities of the speed of information transmission and information investigation are expanding. In addition, the information might be separated at once hub may get to be distinctly basic post handling information. Consequently, how to get a handle on the connection amongst information and precisely decide the convenience and viability of information turns into a genuine test.
b) Data Analytics
Information examination is certainly not another issue. Customary information examination is principally propelled for organized information source, and right now has a total and successful framework. On the premise of the information distribution center, it assembles an information solid shape for online logical preparing (OLAP). Information mining innovation makes it conceivable to discover further learning from a lot of information. Be that as it may, with the entry of the time of enormous information, the volume of various semi-organized and unstructured information quickly develops, which conveys gigantic effect and difficulties to the customary examination strategies and existing procedures are no longer relevant. It for the most part reflects in convenience and file outline under element condition.
i. Timeliness of information preparing
In the period of huge information, time is esteem. As time passes by, the estimation of information contained in the information is too weakening. Progressively information frameworks, time is required higher. For instance, in an information preparing of debacle examination, continuous fast prepares, airplane and other high opportuneness execution gadget, time has gone past monetary esteem. Harms brought about by absurd postponement would be difficult to assess. The period of constant huge information proposes another and higher necessity to the courses of events of information handling, for the most part in the choice and change of information preparing mode. Continuous information handling modes fundamentally incorporates three modes: gushing mode, clump mode and a mix of two-a blended handling mode. Albeit as of now numerous researchers have made an incredible commitment to continuous information preparing mode, yet there is no regular structure for constant handling of expansive information.
ii. Record plan under element condition
The information design in the period of enormous information might change always as information volume shifts and existing social database file is no longer relevant. Step by step instructions to plan a basic, proficient and ready to rapidly make an adjustment has turned into a one of the real difficulties of enormous information preparing when information mode changes. Current arrangement is essentially fabricated a list by NoSQL databases to take care of this issue, yet they have been notable take care of the demand for constant handling of enormous information.
Data privacy issues associated with the advent of computers has been in existence. In the era of big data, the Internet makes it easier to produce and disseminate data, which makes data privacy problems get worse, especially in real-time processing of large data. On the one hand, it requires data transmission real-time synchronization; on the other hand, it demands strict protection for data privacy, which both raise new demands to system architecture and computing power.
i. Expose hidden data
With the appearance of the Internet, especially the appearance of social networks, people are increasingly used to leave data footprints. Through data extraction and integration technology, accumulate and associate these data footprints may cause privacy exposure. In real-time big data processing, how to ensure the speed of processing a data as well as data security is a key issue which has troubled many scholars. Data disclosure conflicts with privacy protection by hiding data to protect privacy it will lose the value of data; thus it is essential to public data. Especially by digging accumulated real-time large-scale data, we can draw a lot of useful information, which has a great value. How to ensure the balance between data privacy and data publicly is currently in research and application a difficulty and hot issue. Therefore, the data privacy in the era of big data is mainly reflected in digging data under the premise of not exposing sensitive information of the user. Paper proposed privacy preserving data mining concept, and many scholars have started to focus on research in this area. However, there are is a conflict between the amount of information and the privacy of data, and that's why so far it has not yet a good solution. A new differential privacy method proposed by Dwork may be a way to solve the protection of data privacy in big data, but this technology is still far from practical applications .
d) Usability issue of data management
Its difficulties for the most part reflect in two viewpoints: gigantic information volume, complex examination, different outcome shapes; various businesses required by huge information. However, examination specialist's absence of learning of both perspectives generally. Accordingly, the ease of use of constant huge information administration principally
Deceivability requires the utilization of the information and the outcomes be indicated unmistakably in an exceptionally instinctive manner. The most effective method to accomplish more techniques for vast information handling and instruments rearrangements and mechanization will be a noteworthy test later on. Ultra-substantial scale information representation itself is an issue, while constant perception of huge scale information will spend a considerable measure of registering assets and GPU assets. Subsequently how to upgrade the execution and use of the GPU is an intense test.
ii. Mapping
Instructions to coordinate another huge information preparing strategy to handling strategies and techniques individuals have turned out to be usual to and accomplish quick writing computer programs is an extraordinary test to information ease of use later on. For Map Reduce needs SQL-like standard dialect, the scientists built up a more elevated amount dialects and frameworks. Run of the mill agents are the Hadoop Hive SQL [32] and Pig Latin [38], Google's Sawzall [39], Microsoft's SCOPE [40] and DryadLINQ [41] and also MRQL [42], and so on. Be that as it may, how to apply these dialects and frameworks to ongoing enormous information preparing still stay huge difficulties.
iii. Feedback
Criticism configuration permits individuals to monitor their working procedures. Works about this perspective is few in Big Information field . In the period of huge information, the inner structure of many apparatuses is exceptionally mind boggling. Also, in programming investigating it is like Black Box troubleshooting for the typical clients and the strategy is unpredictable and additionally need of input. On the off chance that later on human-PC collaboration innovation can be presented in the weight of huge information, individuals can be all the more completely required in the entire investigation prepare, which will successfully enhance the client's criticism sense and extraordinarily enhance the usability.
An outline meets the over three standards will have the capacity to have a decent convenience. Perception, human-PC collaboration and information because systems can successfully improve ease of use. Behind these innovations, gigantic metadata administration needs our unique consideration . So how to accomplish a proficient administration of the enormous metadata in a huge scale capacity framework
i. High many-sided quality of framework
Constant enormous information is exceedingly heterogeneous in information design and in addition equipment and programming and it is hard to model every single huge dat items with a uniform model. Continuous enormous information framework requires high opportuneness which makes it difficult to remove a delegate client conduct progressively. What's more, information size is substantial and information is extremely hard to imitate which both make the test more troublesome.
ii. Rapid upset of framework
The customary social database framework design is moderately steady, however the information continuously enormous information preparing is in a consistent condition of development, and there is a sure relationship between the information, which makes the benchmark test comes about got soon not mirror the present framework real execution. Continuously enormous information framework test results are required to be finished inside a brief timeframe delay with high exactness, which in the equipment and programming angles is a genuine test to the test benchmark.
Reconstruct or reuse existing test benchmark Extend and reuse on the current benchmarks will significantly decrease the workload of building another vast information test benchmark. Potential applicant's principles are SWIM (Measurable Workload Injector for Map Reduce) [48], MRBS [49], Hadoop possess Grid Mix [50], TPC-DS [51], YCSB++ [52], and so on. In any case, these benchmarks are no longer relevant continuously enormous information preparing. Presently there are as of now some explores concentrating on the development of huge pieces of information test benchmark, yet there is additionally a view which thinks its untimely to talk about that at present. By following and investigating the heaps of seven items which are connected with Map Reduce innovation, Chen et al [47] [53] think it is difficult to decide ordinary client situations in the period of huge information. When all is said in done, building huge information and constant huge information test benchmark is vital. In any case, the difficulties it will face are a considerable measure, and it
Fig. 1: The framework of the Map Reduce Model
IV. SHORTCOMINGS OF CLOUD COMPUTING ARCHITECTURE
a) Cloud Computing Overview
Cloud computing is the product of the traditional computer technology and network technology development integration such as grid computing, distributed computing, parallel computing, utility computing, network storage, virtualization, load balancing, etc., which aims at integrating multiple relative low-cost computing entities into one perfect system with powerful computing ability via the network and with the help of the SaaS, PaaS, IaaS, MSP and other advanced business models distributing this powerful computing ability to the hands of the end user.
b) Shortcomings of cloud computing architecture
MapReduce model is simple, and in reality, many problems can be represented with MapReduce model. Thus MapReduce model has a high value as well as many application scenarios. But MapReduces achievement is mainly relying on the Hadoop framework while the data processing method of Hadoop is "Store first post-processing" which is not applicable to real-time large data processing. Though currently there are some improved algorithms able to make Hadoop-based architecture almost real-time, for example, some latest technology like Cloudera Impala is trying to solve problems of processing real-time big data on Hadoop the batch processing of Hadoop and its structural features make Hadoop defective in processing big data in real time. Hadoops defect in real-time big data processing mainly reflects in data processing modes and application deployment. This paper will discuss these two aspects separately in the following.
Big data processing mode can be divided into stream processing and batch processing. The former is store-then-process, and the latter is straight-through-processing. In stream processing, the value of data reduces as time goes by which demanding real-time; in batch processing, data firstly is stored and then can be
c) Other architectures
Except the Hadoop-based real-time big data processing architecture, researchers already design an architecture to deal with a streaming data based on the way to process the stream-oriented data, noticing that batch processing in Hadoop can't meet the feature of real-time big streaming data. For example, Twitters Storm processing mode, Apaches Spark and LinkedIn In-stream.
Spark, as an advanced version of Hadoop, is a cluster distributed computing system that aims to make super-big data collection analytics fast. As the third generation product of Hadoop, Spark stores the middle results with internal storage instead of HDFS, improving Hadoops performance to some extent with a higher cost. Resilient Distributed Dataset, RDD, is an abstract use of distributed memory as well as the most fundamental abstract of Spark, achieving operating the local collection to operate the abstract of a distributed data set. Spark provides multiple types of operations of data set which is called Transformations.
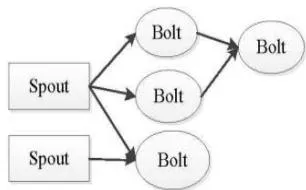
Storm cluster has some similarity with Hadoop. The difference is that its Job in MapReduce running in Hadoop cluster and Topology in Strom. Topology is the highest-level abstract in Storm. Every work process executes a sub-set of a Topology, which consists of multiple Workers running in several machines. But naturally the two frameworks are different. Job in MapReduce is a short-time task and dies with the tasks ending but Topology is a process waiting for a task and it will run all the time as system running unless is killed explicitly. In Storm cluster, it also has Master node and Worker node.
V. REAL-TIME BIG DATA PROCESSING FRAMEWORK
In addition to powerful computing ability, real-time big data processing system must have strong timeliness which means it must quickly respond to the request from system terminals in a very short time delay. So at first, real-time big data processing system must have powerful computing ability for big data. A traditional method to process big data is to rely on the powerful computing capabilities of the cloud computing platform to achieve, while for the timeliness it must rely on the ability of the rapid data exchange between system's internal and nodes.
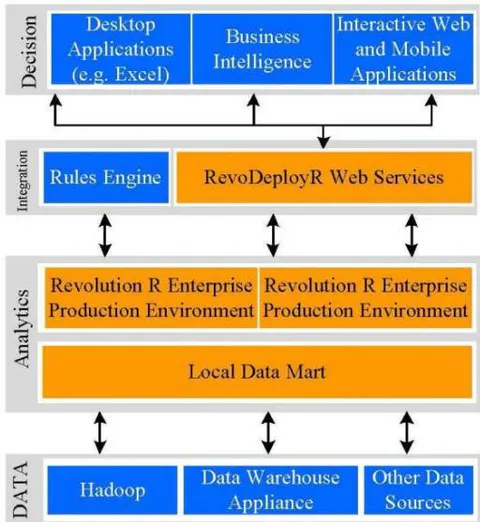
RTDP (Real-Time Data Processing) framework into four layers—Data, Analytics, Integration and Decision from a functional level. Shown in Figure 5.
a) Data
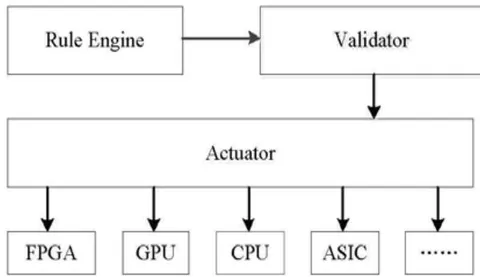
This layer mainly charges for data collection and storage, but also including data cleaning and some simple data analysis, preparing data for Analytics. At the terminal of data collection, it needs to manage all terminals. For example, the FPGA commonly used in Data Stream Management System, DSMS; the ASIC used in Complex Event Processing, CEP; and CPU and GPU (Graphic Processing Unit) in batch processing system represented by MapReduce. Data storage module is responsible for the management of large-scale storage systems. Thanks to the heterogeneity of real-time data sources and the large data processing platform, RTDP systems can handle data from various data sources, including Hadoop for unstructured storage, the data warehouse system for structured storage and analysis, SQL databases, and some other data source system.
This layer makes decisions with the results of data analysis which is the highest layer of data processing system as well as the ultimate goal of data analysis process. RTDP is a procedure involving numerous tools and systems interact with each other iteratively. At every level, the definition of "Big data" and "Real time" is not immutable. They have their own unique meaning at every level due to the functional association at each level. The four layers will be general process of RTDP in the future as well as the basic framework of the RTDP in this paper. Here we are going to discuss each layer in detail from the functionality, processing methods, related tools and deployment aspects of the system.
b) Data Layer
Since the data collected by sensors is rough and messy, and original data often contain too much useless data, modeling and data analysis for the tremendous difficulties, so the data collection process must be preliminary data analys is and filtering. First need to extract the data features, integrated data sources, extraction points of interest, select the characteristic function to determine the data formats and extract useful information from data marts, and several steps in which the data feature extraction for
c) Data Collection and Data Base
RTDP systems heterogeneous platforms and performance makes RTDP system's data source contains a variety of ways, according to the data processing mode can be roughly divided into the CEP, DSMS, DBMS, based on a variety of ways such as MapReduce batch for each treatment have their different data acquisition techniques, such as remote medical field for surgical treatment of complex event processing scenarios for data acquisition ASIC, decoding audio and video coding in an FPGA, etc. Thus, during the data collection and management there are certain rules that must be collected on the side of the device identification, and can be based on different device programming overhead deployment and management nodes.
d) Data Storage and Cleaning
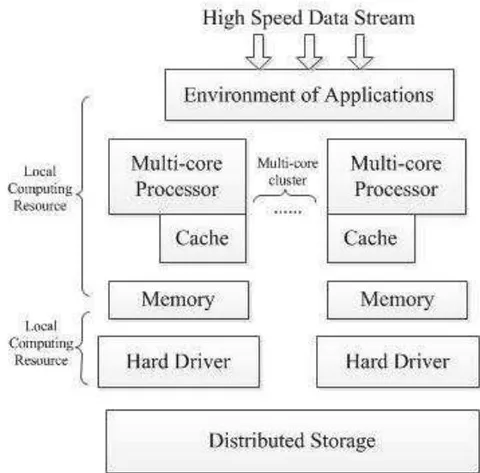
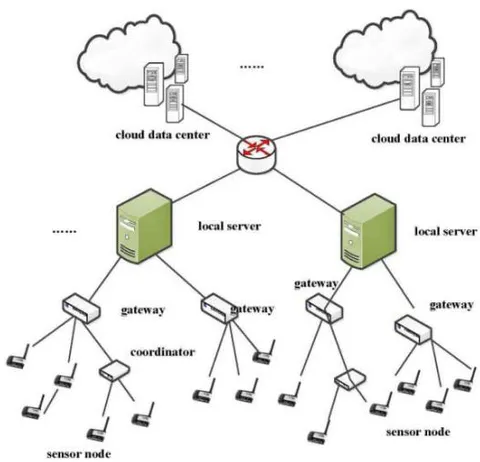
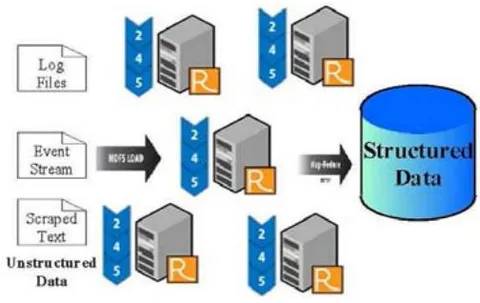
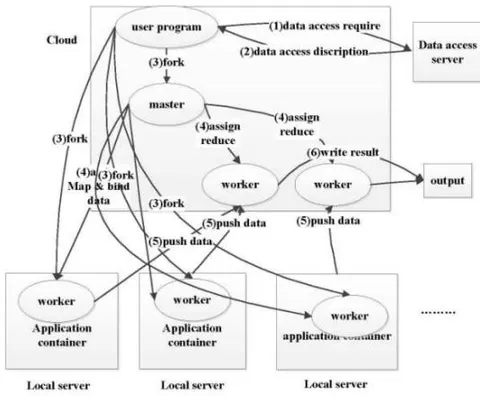
In RTDP, data comes from a wide range of sources, unstructured and structured data mixed, so Hadoop and other unstructured storage system in RTDP system has a natural advantage, but Hadoop itself does not achieve full real-time requirements, which determines our in real-time using Hadoop big data storage process Hadoop first need to solve real-time problems in the framework of the proposed RTDP use of multi-level storage architecture to solve the problem, its architecture is shown in Figure 8.
e) Calculation Implementation Method
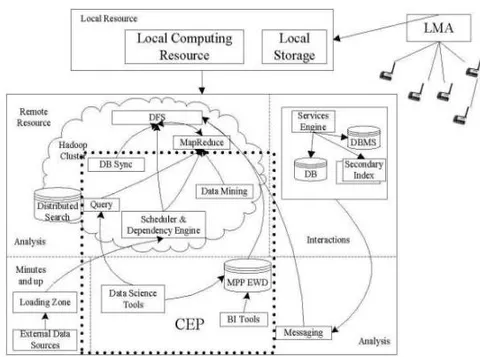
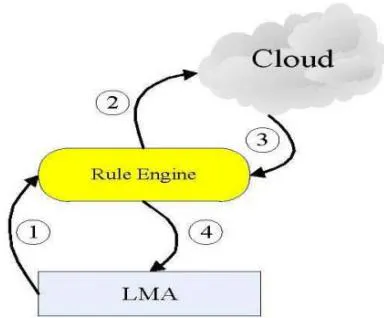
In previous chapters, a two layers' calculation mode has been proposed, first, the local server choose local node management and calculation procedures on the local node management, and simple data cleansing and structured modeling according to LMA. Unstructured data collected by data collector will be transformed into structured data and then uploaded to cloud memory systems and mapped to different management servers. Superstardom makes use of the computing power of cloud terminal to carry through real-time computation and analyze.
f) Decision Making Layer
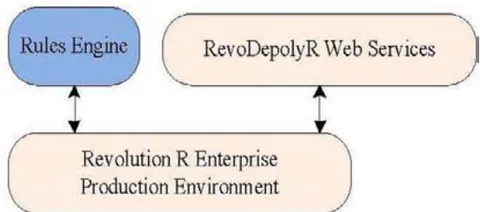
Truth be told, basic leadership layer incorporates two sections of ideas, to begin with, the test and refresh the model, the second is to give administrators to basic leadership. RTDP framework amid the procedure of information handling, with the stream of information, the information at various circumstances with a specific changeability, and between information likewise has a specific pertinence. subsequently change with time and profundity
VI. APPLICATION EXAMPLES
What's more, application area related RTDP explore has likewise got a great deal of consideration, and have made some preparatory research. IBM in 2010 formally proposed "shrewd city" vision and from that point forward a vast continuous information and research to get savvy city boundless consideration as urban framework concentrates canny transportation, brilliant matrix, and urban administrations identified with therapeutic insight has likewise been an incredible improvement. Different applications have their own particular one of a kind quality, many key issues still uncertain, a hefty portion of the current zones most important reviews likewise stay in the research facility stage. A case of RTDP shrewd matrix keen lattice framework in the application review will be made underneath.
Savvy lattice through countless time sensor detecting framework operation state changes, can give quicker element assessment of constant blame conclusion and vitality tracking in covering areas, districts and even across the nation dynamic direction of vitality to accomplish conveyance vitality creation with sensible dispatch, for enhancing vitality effectiveness, enhancing urban foundation assumes an essential part.
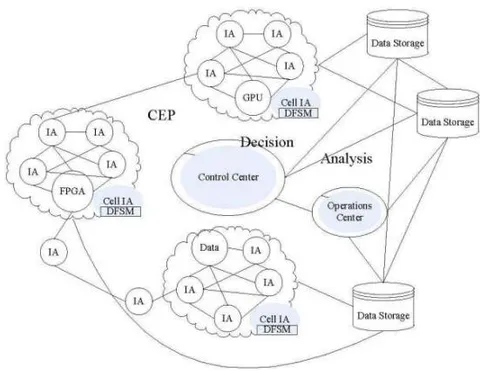
The various specialized challenges are all inside the extent of the entire system and information identified with checking and constant computation, so this paper the answer for the present field of keen lattice of the key issues, we should depend RTDP handling structures for expansive scale organize wide continuous information joining the proposed RTDP structure to fabricate another sort of shrewd network design, appeared in Figure 15.
Quick reenactment and demonstrating is the center programming of ADO, including hazard evaluation, self-mending and other propelled control and advancement programming framework for the savvy lattice to offer help and prescient numerical capacity, keeping in mind the end goal to accomplish enhanced network strength, security, dependability and operational productivity. Dispersion quick recreation and demonstrating need to bolster arrange reconfiguration, voltage and responsive power control; blame area, separation and reclamation of power; when the framework topology changes taking after the security re-tuning four self-mending abilities. Above capacity interconnectedness, coming about DFSM turn out to be extremely convoluted, for instance, either a network reproduction requires another hand-off with voltage control or the new celebration program likewise incorporates capacities to reestablish control. DFSM by means of dispersed insightful system specialists to accomplish hierarchical limits crosswise over geological limits and canny control framework keeping in mind the end goal to accomplish self-mending capacities of these keen system operators, ready to gather and trade data and frameworks, (for example, the accompanying such electrical insurance operation) nearby control choices, while as indicated by the framework prerequisites to facilitate these projects.
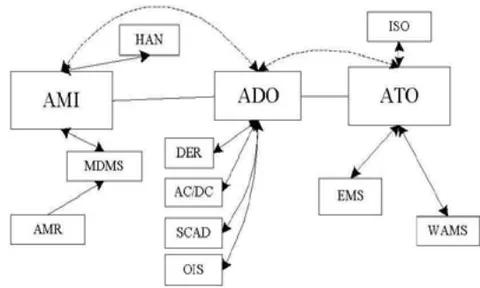
Shrewd Grid unwavering quality issues contemplated by the AC transmission hardware for blunder infusion approach the gear disappointment mode investigation. Disappointment of the hardware and on its impact and power network unwavering quality were surveyed. writing demonstrates that the present development of brilliant framework mix of utilizations and innovation arrangements, including savvy meters, correspondence systems, metering database administration (MDMS), client premises organize (HAN), client benefit, remote turn on or off, as appeared in Figure 14, keen lattice advancements has achieved a specific level of accessibility and adaptability, however in the force of constant sending, administration, blame location and recuperation, there are still deficiencies.
VII. CONCLUSION & FUTURE WORK
Real-time data processing for large current technology is undoubtedly a huge challenge, there is lack of support for massive real-time processing of large data frame and platform real-time processing of large data processing compared to conventional static data with high data throughput and real-time requirements. cloud computing technology in order to solve massive data processing and developed a series of techniques, however, cloud computing is very suitable for mass static, long-term without the written data has a good effect, but it is difficult to achieve real-time processing.
In this paper, on the basis of cloud computing technology to build a kind of real-time processing of large data frame, the model proposed RTDP four architecture, and hierarchical computing model. RTDP system in order to meet real-time requirements, and to consider different system platforms RTDP structural characteristics, the paper also presents a large data storage for real-time multi-level storage model and the LMA-based application deployment methods of data collection terminal based on the different ways of data processing were used DSMS, CEP, batch-based MapReduce other processing mode, depending on the environment in which the sensor data acquisition and the desired type of difference data collected were used FPGA, GPU, CPU, ASIC technology to achieve data collection and data cleansing and, through a structured process the data structure modeling, uploaded to the cloud server for storage, while the washed structured data on the local server for Reduce, combined with powerful computing capabilities cloud architecture for large-scale real-time computing with MapReduce.
This thesis indicates generally that the basic framework for future RTDP system and basic processing mode, but there are still many issues that need further study. The main point are as follows:
- Determining the appropriate mode of calculation in a RTDP system, as well as determining the data processing mode and approach, is a key factor in determining system performance. Therefore, designing the future core work involves determining the appropriate method of calculating the design.
Calculation models and how to achieve unity between computing technology is currently used mainly batch calculation mode and streaming processing, data computing model in determining how to design the corresponding calculation after the manner and with what kind of hardware implementation is the next big real-time data processing priority;
How to ensure the network transmission speed and QoS (Quality of Services); now widely used in a variety of network QoS technology, RTDP not sufficient to ensure a real-time, high reliability requirement. RTDP network QoS issues RTDP with difficulty from the inherent characteristics, so to guarantee QoS of the real-time RTDP sex have a significant impact;
Ensuring the system's physical time synchronization is a future research direction. RTDP systems involve many interactions between systems and tools, and software used for real-time marker approaches does not meet the high real-time requirements of future RTDP systems. How to ensure data during physical time synchronization is a significant challenge.
How to ensure the correctness of the data processing. Error detection mechanism and automatically repair the computer has long been a difficult area of research, how to handle the data detection and error diagnostic and system repair is a huge project.
RTDP is a complex project involving many disciplines and techniques to be thorough in all aspects of research, pointed out that the article provides an overview of future research directions, and this is our future research subject.