



1. Introduction
Solving linear PDE problems frequently involves solving a linear system of equations using iterative algorithms. A central aspect in designing such iterative solvers for a linear system of equations is finding an approximation of , referred to as a preconditioner. The simplest method to utilize a preconditioner is through iterative refinement, also known as Richardson iteration or deferred correction:
One step of the Richardson iteration method only requires one multiplication of a vector by the matrix , making it suitable for large systems of equations.
The Helmholtz equation is given by
For sufficiently large , the operator is not positive definite [5]. Furthermore, if absorbing boundary conditions are imposed, is no longer symmetric. It is well known that Richardson iteration with standard solvers like Gauss-Seidel, Jacobi, or geometric multigrid diverge when applied to non-symmetric or non-positive definite operators. In such cases, more involved techniques are required, e.g., domain decomposition methods [3, 8, 9], Krylov-type methods [5, 7] including the generalized minimal residual method (GMRES) and its variants [2, 23, 25], and GMRES with shifted Laplacian preconditioning [6]. However, computational cost and memory storage are more expensive for these methods.
A possible remedy that still allows the use of (1.6) is finding a non-linear preconditioner, , using a neural network architecture named Deeponet [19], which has been experimentally proven to be a robust architecture for learning operators between function spaces, and in particular, for learning solutions of partial differential equations. The classical Deeponet receives as an input and a function defined on and returns . The representation of by finite-dimensional can be done most straightforwardly by evaluating on points in . The classical Deeponet admits the following general form: Let be the values of over fixed points in . Let and be neural networks such that
Then
The network is named the trunk and is named the branch. The network is trained over data samples such that the loss function
is minimized over all samples. The structure of (1.3) is a classical structure of data-driven recommender systems [26].
One of the drawbacks of Deeponet is that the numerical accuracy of solutions for a linear system is not fully understood, and reducing the error requires improved architectures [28]. In general, solutions with errors of machine precision are not possible. To overcome the latter difficulty, a novel hybrid, iterative, numerical, and transferable solver (HINTS) has been recently developed [27]. The hybrid solver uses Deeponet as a preconditioner and is integrated inside existing numerical algorithms (e.g., Jacobi, Gauss-Seidel, multigrid) to obtain higher convergence rates for solutions of linear systems arising from discretizations of PDEs up to machine precision. Classical preconditioners reduce the residual’s high-frequency mode. HINTS balances the convergence behavior across the spectrum of eigenmodes by utilizing the spectral bias of Deeponet, resulting in a uniform convergence rate, giving rise to an efficient iterative solver. This assertion has been recently further investigated in [17], and the robustness of Deeponet-based preconditioners for iterative schemes of linear systems has been shown. We emphasize that Deeponet is trained over a low-resolution grid but provides robust preconditioners for higher resolutions without further training.
A drawback of Deeponets, and as a result also of HINTS, is that it is not geometry aware. Hence, Deeponet trained on a reference domain might not be efficient for problems on different domains, which are not only small perturbations of the reference domain [15]. The direct solution is modifying Deeponet to train using data from different geometries and multiple domains [10, 12, 13, 14, 16, 24]. Yet, as data generation for thousands of domains is time-consuming, we aim to avoid this approach, which might be overkill when using Deeponet as a preconditioner in HINTS.
In [15], a state-of-the-art (SOTA) vanilla Deeponet has been demonstrated to operate robustly when used inside HINTS on different domains by extending to be for points outside the required domain. Though this approach does not require additional training on multiple domains, it fails to converge in multiple examples we will demonstrate, and training on multiple domains is necessary.
Another potential drawback of the vanilla Deeponet is its convolutional neural networks (CNN). Though convolutional neural networks have obtained remarkable capability for studying images and functions on rectangular grids, in the problems studied by [10, 12, 13, 14, 16, 24], it becomes impractical for several 2D/3D problems and several networks excluding convolutional operations were suggested.
In this work, we strive to use HINTS, also obtained from a non-convolutional and geometry-aware Deeponet, to improve existing iterative schemes to solve problems on different domains even though the training is only on simple geometries. We avoid using CNN operations for two reasons: First, we would like to avoid any artificial extension of a function outside its domain. Second, we wish to provide a network that could be used on problems where convolutional operations are impractical.
1.1. Problem Formulation and Novelties
We consider the following problem:
where is a piecewise smooth domain. Again, we stress that this problem is non-definite for sufficiently large and non-symmetric. See [4] Chapter~35 for well-posedness. Standard second-order finite-difference discretization of (1.4) leads to a system of linear equations of the form
We consider the following Richardson-type iterations to solve (1.5):
where and is some preconditioner. The matrix with given by (1.4) can be non-definite and, in general, cheap methods such as Jacobi/Gauss-Seidel diverge. As noted by [27], can be obtained using a neural network , estimating the inverse operator of (1.4) and leading to convergence of (1.6) by using the hybrid method
where and is any classical iterative update rule (e.g., Gauss-Seidel, GMRES). Our goal is to replace by a neural network such that the resulting scheme (1.7) applies to families of geometries that are not necessarily “similar” to the reference geometry used in training without further fine-tuning of the neural network.
Remark 1.1. Deeponet receives as an input a function, and therefore can handle functions defined on different grids when the input function is sampled over a finite number of points. By interpolating the input function, Deeponet trained on a certain grid can still handle input data over a coarser or finer grid. When using coarser/finer grids that contain grid points used for training, the interpolation process is immediate as it requires only choosing a subset of the sample points. Therefore, when one uses Deeponet on different grids, it is less expensive to include grids which include the grid used for training.
Generating training data requires solving (1.4). So, generating data for multiple geometries can be very expensive and challenging when dealing with complex geometries. Our goal is to generate data on simple geometries only (e.g., rectangles), and then test (2.3) on different geometries without any further fine-tuning for different geometries (cf. [11]). As the neural network takes inputs of fixed sizes, one has to account for dealing with domains with different amounts of grid points. Moreover, one has to deal with how to order the points inside each domain. Another problem is how one can evaluate on by computations that “ignore” all points outside , since the non-homogeneous term in (1.4) is not defined outside .
1.2. Main Novelties
We present a new architecture for learning the solutions of (1.4), which accounts for the domain’s geometry. Our model is a novel improvement to the vanilla Deeponet as it significantly improves the geometry transferability, in case the vanilla model might fail. To be more specific, our network is trained on data generated from solutions to (1.4) on simple reference geometries and still produces robust iterative schemes for different subgeometries using (2.3), without additional training or fine-tuning (cf. [11]). We examine scenarios where HINTS with vanilla Deeponet diverges while our network converges.
While common layers in Deeponet are mainly linear and convolutional layers, we also use masked self-attention layers [22]. The masked self-attention layers enable us, during evaluation on an arbitrary geometry with an arbitrary number of grid points, to include only the points that belong to . This approach does not require an artificial extension of outside to fit the input size of the network (cf. [15]). We observed that when narrow cracks appear in the tested geometries, the masking effect becomes significantly noticed and outperforms the vanilla model.
We compare our approaches with the vanilla Deeponet and a naive extension of the vanilla Deeponet to a geometry-aware Deeponet with CNN layers. The latter model is presented to demonstrate that our problem is not only a trivial extension of the vanilla case.
To our best knowledge, this is the first attempt to learn preconditioners using geometry-aware neural networks, and integrating them with classical iterative solvers.
1.3. Notations and Symbols
We use the following symbols and notations:
For , is the statistical standard deviation.
For , .
For , is the pointwise multiplication product of .
denotes the grid size in a spatial two-dimensional discretization of the unit square for points.
is the skip factor in (2.3).
is a positive constant in the Helmholtz equation (1.2).
GMRES corresponds to the GMRES algorithm (Algorithm 3 in [23]).
Hints-GS() is the application of (2.3) where is a single application of the Gauss-Seidel updating rule.
Hints-GMRES() is the application of (2.3) where corresponds to iterations of the GMRES algorithm.
2. Resources and Techniques
In this section we describe in detail our proposed geometry-aware Deeponet model.
2.1. The Model
We generate a uniform grid on with points. We flatten the grid points to obtain a vector .
Model’s inputs:
.
A domain represented by vector , where
and is the signed distance function.
A real function , represented by the complex vector , where
A masking matrix defined as follows:
.
Model’s output: a complex number representing the solution to (1.2) evaluated at .
2.1.1. Model’s Layers
First, we define the M-attention operation of and to be
(see [22]). The function is defined by
Notice that the M-attention does not depend on the values of outside . If the masking matrix is replaced with a zero matrix, then M-attention accounts for a trivial extension of outside and, therefore, depends on the extension one chooses for outside .
Since the output of the model should be a complex number, we first define two Deeponets, and , having the structure (1.3) with the following branch and trunk:
Branch:
defined by the operation of -attention on the matrix generated by concatenating and followed by a dense neural network with a activation.
Trunk:
defined by the operation of a dense neural network (NN) with layers and activation function [12], on the vector generated by concatenating and .
We construct a neural network:
We also define a second network:
where the masking matrix is replaced by the zero matrix, and an input function is extended by zeros outside its domain.
We define an updating rule for the hybrid method called HINTS, as follows:
where and are (non-trained) hyper-parameters to be selected by the user, and is the iteration number. The normalization factor ensures that the input of the network will belong to the distribution of the training data.
Remark 2.1. We have defined our networks to consider as inputs only real functions. In order to apply () to complex functions, one can apply the same network separately to the real and imaginary parts of .
2.2. Model’s Training Data
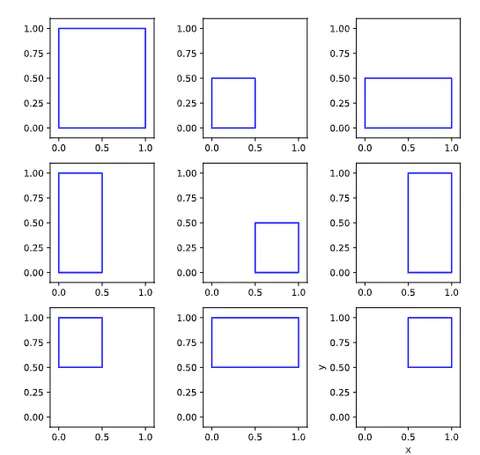
We fix . Then, we discretize each of the training geometries in Figure 1 with a uniform grid of grid size . The training data for is obtained by solving (1.4) on the geometries in Figure 1 using a standard second-order finite difference method, with 300 different functions , taken to be Gaussian random fields over with zero mean and covariance kernel
where .
2.3. Network Complexity
Every iterations of the classical iterative method is followed by one application of . As the network’s input is a vector of fixed dimension, each evaluation of the network on a single data point is of constant computational and memory complexity. As a result, for a sparse (and band-limited) linear system of order , the complexity of each iteration involving in (2.3) is for both memory and computational complexity.
3. Results
We compare the performance of HINTS (2.3) using numerical simulations for four different models:
is given by (2.1) and was trained on geometries in Figure 1.
is given by (2.2) and was trained on geometries in Figure 1.
Vanilla DeepONet taken from [27] (see Appendix 4) and was trained on .
ga-vanilla is a naive implementation of geometry-aware DeepONet using CNN (see Appendix 4) that was trained on the geometries in Figure 1.
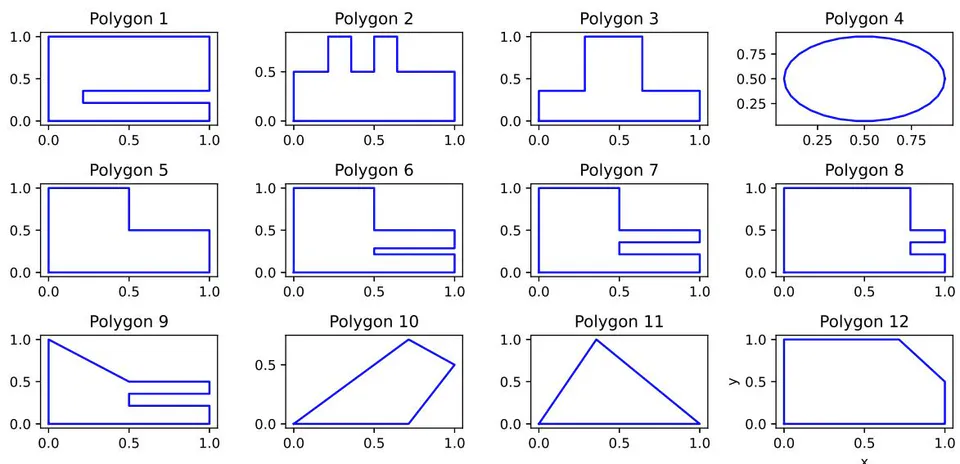
Our tested geometries for problem (1.2) are presented in Figure 2. We discretize each tested domain with a higher resolution than the resolution used for training, . We solve (1.4) using (2.3) with a random function , sampled from another distribution than the one used for training ( has been generated as a vector from a normal distribution with mean ten and variance 10). Since the neural network operates on the error terms only, the distribution of does not affect the hybrid scheme’s robustness. We compare our method with both Gauss-Seidel iterations (see Table 1) and GMRES iterations (see Table 3). The main advantage of Gauss-Seidel (GS) is that, for sparse systems, it has linear complexity in both memory and computational time. However, GS does not always converge for the non-definite cases in our examples. We will show that Hints-GS converges even when plain Gauss-Seidel iterations diverge.
| Method | Model | Iter. number | |
|---|---|---|---|
| Geometry 1 | |||
| H-GS() | 4877 | ||
| H-GS() | ga-vanilla | diverge | |
| H-GS() | vanilla | diverge | |
| H-GS() | diverge | ||
| Geometry 2 | |||
| H-GS() | 12000 | ||
| H-GS() | ga-vanilla | diverge | |
| H-GS() | vanilla | diverge | |
| H-GS() | 16000 | ||
| Geometry 3 | |||
| H-GS() | 2157 | ||
| H-GS() | ga-vanilla | 1616 | |
| H-GS() | vanilla | 1325 | |
| H-GS() | 1381 | ||
| Geometry 4 | |||
| H-GS() | 1519 | ||
| H-GS() | ga-vanilla | diverge | |
| H-GS() | vanilla | 813 | |
| H-GS() | 764 | ||
| Geometry 5 | |||
| H-GS() | |||
| H-GS() | ga-vanilla | diverge | |
| H-GS() | vanilla | 1064 | |
| H-GS() | 842 | ||
| Geometry 6 | |||
| H-GS() | 6300 | ||
| H-GS() | ga-vanilla | diverge | |
| H-GS() | vanilla | >20000 | |
| H-GS() | 7200 | ||
| Geometry 7 | |||
| H-GS() | 10800 | ||
| H-GS() | ga-vanilla | diverge | |
| H-GS() | vanilla | diverge | |
| H-GS() | 8034 | ||
| Geometry 8 | |||
| H-GS() | 2028 | ||
| H-GS() | ga-vanilla | 2400 | |
| H-GS() | vanilla | 1370 | |
| H-GS() | 1617 | ||
| Method | Model | Iter. number | |
|---|---|---|---|
| Geometry 9 | |||
| H-GS() | 9700 | ||
| H-GS() | ga-vanilla | diverge | |
| H-GS() | vanilla | diverge | |
| H-GS() | 18500 | ||
| Geometry 10 | |||
| H-GS() | 2500 | ||
| H-GS() | ga-vanilla | diverge | |
| H-GS() | vanilla | 2450 | |
| H-GS() | 1055 | ||
| Geometry 11 | |||
| H-GS() | 2100 | ||
| H-GS() | ga-vanilla | 1770 | |
| H-GS() | vanilla | 1055 | |
| H-GS() | 1040 | ||
| Geometry 12 | |||
| H-GS() | 1200 | ||
| H-GS() | ga-vanilla | 1000 | |
| H-GS() | vanilla | 940 | |
| H-GS() | 560 | ||
| Method | Model | GMRES iter. | DeepONet iter. | |
|---|---|---|---|---|
| Geometry 1 | ||||
| GMRES | — | 27120 | — | |
| H-GMRES() | 11400 | 130 | ||
| H-GMRES() | vanilla | 11000 | 120 | |
| H-GMRES() | 24797 | 273 | ||
| Geometry 2 | ||||
| GMRES | — | 19416 | — | |
| H-GMRES() | 8500 | 90 | ||
| H-GMRES() | vanilla | 25800 | 285 | |
| H-GMRES() | 7200 | 70 | ||
| Geometry 4 | ||||
| GMRES | — | 21570 | — | |
| H-GMRES() | 5300 | 57 | ||
| H-GMRES() | vanilla | 3824 | 42 | |
| H-GMRES() | 4490 | 48 | ||
| Geometry 6 | ||||
| GMRES | — | 17816 | — | |
| H-GMRES() | 8814 | 96 | ||
| H-GMRES() | vanilla | 13400 | 147 | |
| H-GMRES() | 13079 | 144 | ||
| Geometry 7 | ||||
| GMRES | — | 18426 | — | |
| H-GMRES() | 8800 | 96 | ||
| H-GMRES() | vanilla | 16500 | 190 | |
| H-GMRES() | 15300 | 170 | ||
| Geometry 9 | ||||
| GMRES | — | 14616 | — | |
| H-GMRES() | 8800 | 100 | ||
| H-GMRES() | vanilla | 14600 | 160 | |
| H-GMRES() | 9900 | 108 | ||
| Geometry 11 | ||||
| GMRES | — | 16257 | — | |
| H-GMRES() | 5500 | 60 | ||
| H-GMRES() | vanilla | 4140 | 45 | |
| H-GMRES() | 3830 | 42 | ||
GMRES’s main advantage is proven convergence for any non-singular matrix, while its major drawback is memory complexity. For (not necessarily sparse) linear equations with equations (i.e., corresponding matrix ), the iteration complexity of GMRES after iterations is and the memory complexity is . A possible remedy is the restarted GMRES method, GMRES(), whose memory complexity reduces to independently of the number of iterations but with a possible degradation of convergence rates. We will show that combining GMRES inside (2.3) yields a more efficient method in terms of both time and computational complexity.
It is worth noting that, even when Gauss-Seidel iterations diverge, they are still known to reduce high-frequency errors throughout the iterations. Therefore, Hints-GS highlights the capability of HINTS to effectively control low-frequency modes.
We use the following schemes for comparisons as in (2.3): GMRES, Gauss-Seidel (GS), Hints-GS, Hints-GMRES, see Subsection 1.3. Multiple computations were performed, and we show the mean number of iterations required. is the wavenumber in the Helmholtz equation, is the discretization size, and is the skip factor in (2.3) for how often the neural network (DeepONet) is called.
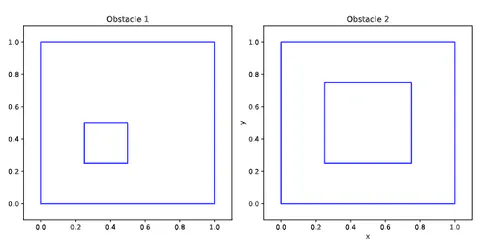
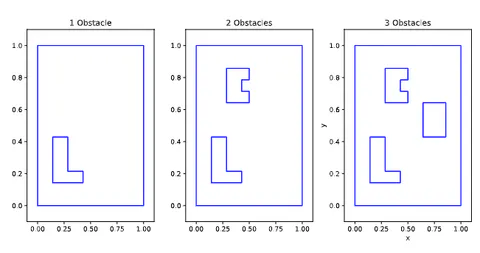
Remark 3.1. One of the highlights of [15] was the generalization capability of the vanilla DeepONet on a difficult obstacle problem. We also performed experiments of problem (1.2) on obstacle problems with and , and observed the superiority of over the vanilla DeepONet (see Table 4). We have also performed additional experiments on exterior domains with different shapes of obstacles (see Table 5).
| Method | Model | Iter. number | |
|---|---|---|---|
| Obstacle 1 | |||
| Gauss-Seidel | — | diverge | |
| H-GS() | vanilla | 18000 | |
| H-GS() | 8000 | ||
| Obstacle 2 | |||
| Gauss-Seidel | — | 10600 | |
| H-GS() | vanilla | >20000 | |
| H-GS() | 3425 | ||
| Obstacle 1 | |||
| GMRES | — | 21400 | |
| H-GMRES() | vanilla | diverge | |
| H-GMRES() | 14100 | ||
| Obstacle 2 | |||
| GMRES | — | 6460 | |
| H-GMRES() | vanilla | 12000 | |
| H-GMRES() | 8100 | ||
3.1. Observations from Tables 1,2,3,4,5
We have demonstrated multiple examples with complex geometries for which HINTS with the vanilla method fails, while our network succeeds. This confirms the necessity of the new models and we presented. In particular, in terms of convergence capability, our new models outperform the vanilla model. Yet, we mention that the geometry transferability of the vanilla model still performs robustly on many domains including non-rectangular ones (geometries 3, 4, 5, 8), and in many cases provides similar or slightly better convergence rates to that of our geometry-aware models.
| Method | Model | Iter. number | |
|---|---|---|---|
| 1 obstacle | |||
| Gauss-Seidel | — | diverge | |
| H-GS() | vanilla | 16700 | |
| H-GS() | 8500 | ||
| 2 obstacles | |||
| Gauss-Seidel | — | diverge | |
| H-GS() | vanilla | >40000 | |
| H-GS() | 14500 | ||
| 3 obstacles | |||
| Gauss-Seidel | — | 12500 | |
| H-GS() | vanilla | 8300 | |
| H-GS() | 8500 | ||
| 1 obstacle | |||
| GMRES | — | 32100 | |
| H-GMRES() | vanilla | 10575 | |
| H-GMRES() | 16480 | ||
| 2 obstacles | |||
| GMRES | — | 18000 | |
| H-GMRES() | vanilla | 14193 | |
| H-GMRES() | 15810 | ||
| 3 obstacles | |||
| GMRES | — | 8600 | |
| H-GMRES() | vanilla | 13343 | |
| H-GMRES() | 16717 | ||
In almost all tests ga-vanilla obtained the worst results, implying that a naive extension of the vanilla model does not work and a more sophisticated approach was required.
When the domain’s boundary contains abrupt changes (cracks/bumps/holes), such as geometries 1, 2, 6, 7, 9, performed better than all methods. In cases for which vanilla outperformed , outperformed , with an exception for H-GMRES for geometry 1.
In almost all cases we tested there is a correlation between HINTS’ performance with different methods (GS, GMRES). Yet, the method used inside HINTS and the corresponding parameters can violate this correlation (e.g., Table 5). In more detail, the experiments with the geometries in Figure 4 show that with GS, outperforms the vanilla method significantly, whereas for the same problem with GMRES () the vanilla method is better. Yet, for a different parameter , H-GMRES with vanilla diverged while it converged with .
We can conclude that the idea of extending a function outside its domain to be 0, as suggested in [15], can indeed provide robust results for different domains as long as the domain does not contain abrupt changes (narrow cracks, holes). In these problematic scenarios our masked model can overcome this limit.
Based on our results, we suggest to a potential user who cannot use CNN operations to hold both and . Further study on unifying these networks is left for future research.
Remark 3.2. The running times of (2.3) can differ for different types of computers. There is room for additional improvement of (2.3) as we did not use a GPU and did not exploit parallel computation of batched data during inference. In our machine, H-GS with higher resolutions than is either very slow or diverges, and therefore we switched to GMRES to obtain faster CPU time.
4. Conclusions, Remarks and Further Research
We have constructed a novel architecture for preconditioning linear equations, which is aware of the geometry of the problem. We showed evidence by numerical examples that our network remains a robust preconditioner for problems with different geometries without any fine-tuning procedure and outperforms existing SOTA methods for tackling similar problems. Another advantage of our proposed network is that it is non-convolutional and therefore can be generalized to non-rectangular grids and point-clouds.
We demonstrated our network on a complex Helmholtz equation with complex boundary conditions, which are hard to solve due to non-definiteness or non-symmetry, and on an obstacle problem.
In future work, we intend to generalize our network to include more attention layers and, with the availability of more advanced hardware, to train the network on a larger number of geometries.
Another possible extension is to modify the neural network so that it is invariant under domain translations, as the PDE is.
Appendix A
Appendix A.1. The Networks
For vanilla DeepONet, trained on a single domain , we employ the architecture in [27] page~37. The branch net is a combination of a 2D CNN (input dimension , number of channels , kernel size , stride 2) and dense NN (dimension ) with ReLU activation function. The dimension of the dense trunk network is with activation of .
For the naive geometry-aware DeepONet (ga-vanilla), we represent the domain as a 2D binary image and pad the values of the function with zeros in all points outside the domain is defined. We then use CNN as in the vanilla DeepONet whose output is concatenated and fed into a dense NN (dimension ), resulting in the branch. The dimension of the trunk network is with the activation of .
Appendix A.2. Data Generation and Training
We fix in (1.4). The vanilla network is trained over 300 solutions of (1.4) in discretized uniformly with . The solutions are obtained by taking to be 300 Gaussian random fields (2.4). The equations are solved using a standard second-order finite difference method. The network ga-vanilla is trained on the same data used to train , see Subsection 2.2.
We trained the networks using PyTorch for 1000 epochs with a batch size of 64, and the initial learning rate decreased by 0.5 at the final epochs.


