I. BACKGROUND TO STUDY
The fundamental Vs of Big Data are volume, velocity and variety [1]. Volume refers to the size of data being created, Velocity is the speed at which data is created, captured, extracted, processed, and stored while variety connotes different data types and sources ranging from structured, semi-structured to unstructured data. Of the three Vs, volume is most directly associated with big data and to put its importance in a perspective that emphasizes its relevance to query optimisation, volume may be redefined as voluminosity, vacuum, and vitality – three additional V-dimensions of data as exposed by [2]. Voluminosity states that there is already a very large set of data collected and even much more is available that can be harvested. Voluminosity speaks of a significant gap that can be filled by data yet to be collected. From the perspective of voluminosity, volume refers to the size of data being created from all sources in an organization including text, audio, video, social networks, research studies, medical data, space images, crime reports, weather forecasting and natural disaster [3].
The vacuum dimension of volume states that there is a strong requirement for storage to store large volumes of data. Due to the fact that the data is acquired incrementally, empty spaces will always be needed for use in the creation of room to store, process and manage tremendous data set as they are harvested from different sources. This dimension of volume pops up the research question about how much storage space is available for incoming data rather than how much data has already been stored. The process of creating storage space for incoming data is equally as challenging as it is with managing vast sets of already stored data. Empty spaces that serve this purpose are created by either augmenting storage devices or techniques used to compress the size of data .
Vitality may be defined as the survival of data in the storage environment and thus its reliability and usefulness. Data in the storage environment falls into the two categories, namely active served and unserved. In a large data bank, some data are actively used while some are not . Vitality redefines volume as meaning that data and its subsets are used actively at different times. While a portion of data may be actively used data at a time or within a specific transaction, the rest are stored for future uses. There is the risk that data stored for future may take so long for it to be used which may lead to such sub-datasets to be abandoned or not properly maintained. As the risk of being abandoned gets higher, anything can happen to those datasets not currently in use. In other words, with less investment and attention to the unserved data, they are exposed to incidences of fire, earthquake, flood, war, and terrorist which are the prominent causes of data loss. Thus, vitality is a critical component of volume. The lack of vitality, in any case, is symptomatic of the absence of disaster management systems which decimates data reliability or can lead to complete data loss. Apart from reliability, vitality also describes flexibility, dependability, and security which are all integral components of volume, As data gets larger in the dimensions of big data, partitioning strategies have been used to reduce the data to smaller subsets over which queries become faster compared to the original dataset . Popular among these partitioning strategies is the horizontal scaling (scaling out), Horizontal scaling refers to resource increment by the addition of complete and independent units that work in unison with an existing system. The additional units may be of smaller capacity, making it cheaper compared to the replacement of an existing single unit with one of larger capacity. The scale out effect of the horizontal partitioning strategy creates a hardware infrastructure platform on which partitioned data is then distributed across multiple units or servers, hence, reducing the excess load of the entire data set on a single machine . This platform comes with the added advantage of keeping the entire system up even if some of the units go down, thus, avoiding the "single point of failure" problem associated with vertical scaling. The vertical scaling (scaling up) strategy refers to increasing the ability of a single hardware unit such as a server to handle the ever-increasing workload as a way of achieving resource increment. From the perspective of hardware, this includes adding memory and processing power to the single unit.
The horizontal scaling strategy is at the heart of the implementation of big data stores namely p-stores, c-stores and NoSql among others that have pioneered the paradigm shift of "No One Size Fits-All" proposed by Stonebraker and Çetintemel [8]. The horizontal scaling strategy partitions data such that queries can be fired selectively on the partitions with the aim of retrieving the desired data in optimal query time. As is applicable to all datasets, the desired data in a partition is indicated in a query using a boolean expression of conditions called predicates. Predicates are used in joins as well in search arguments of queries. A join predicate is a predicate that relates columns of two tables to be joined and the columns referenced in a join predicate are called join columns. When used in Search ARGuments (SARGs), predicates are referred to as sargable predicates [9]. A sargable predicate is one of the form (or which can be put into the form) "column comparison-operator value". Matalqa and Mustafa [5] experimentally demonstrated that restructuring big data into partitions produces query enhancement results. Using the theorem and axiom, Obilikwu, Kwaghtyo and Ogbuju [10] theoretically proved the result of [5] as follows:
Theorem: Given as the partitions of a relation R, then where n = the number of distinct values in the value set associated with the partition key that generated
Axiom: The following axioms are applicable:
- A partition key has a value set, V whose element cannot be null
2. The number of distinct values of V is n= number of partitions produced
Proof: Let 6 be the partition predicate associated with a distinct value of V, then Arity(6) is the arity of the tuples filtered by 6.
Given any value of, there exists, wherefilters all tuples infrom relation.
filters all tuples in from relation R, and
filters all tuples in from relation R,
Since the elements of V cannot be null, then Arity(V) = Arity(R)
Since filter the tuples of R according to the distinct values of V, it follows that
This implies that since n is the number of distinct values of V defined in R
This shows that since filter the tuples of R. QED.
The use of partitioning strategies makes queries faster . This is because retrieving a record or a set of records from a relation is done relative to the number of the total number of records in the relation (R). Based on this relationship, query time can be computed as a ratio using equation 1.
where is query time, is the number of tuples retrieved from a relation R using a predicate and is number of tuples in R. Equation 1 assumes an asymptotic value of as well as the fact that other factors that affect query time are held constant. Among others, these other factors are processor speed, RAM and ROM size, communication traffic and code efficiency.
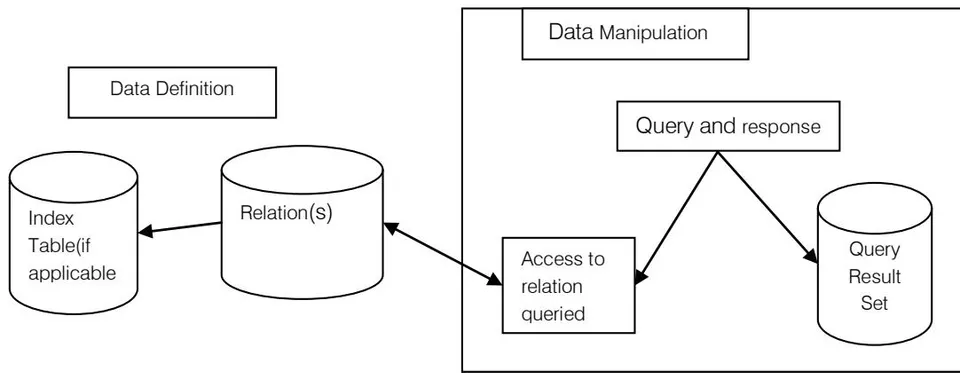
The implication of equation 1 is that an increase in volume implies an increase in query time. The query works with the DBMS as part of the algorithms that ensure data is retrieved seamlessly. While the DBMS suggests how the data can be located and retrieved, the query syntax tells what data is to be retrieved. These make up the two components of a database management system as depicted in Figure 1.
This paper is motivated by the critical need to optimise queries in the context of big data, big data being a development that has led to the ubiquitous incidence of big databases. The objectives of the paper are therefore as follows: (i) show that query time increases as the arity of database storage structures increase; (ii) show that optimising query time can be approached by organizing the storage structure using techniques like indexing and storage partitioning. It is also shown that queries can be modified or transformed to an equivalent form such that query time is reduced; (iii) use a combination of mathematical techniques to develop the concatenated predicate model thus enhancing the query time of sargable conjunctive equality predicates (iv) prove using mathematical induction and other applicable techniques that the concatenated predicate model optimises the sargable conjunctive equality predicate.
The rest of this paper is organized as follows: Section 2 reviews literature on the general concept of query optimisation and subsequently narrows the discussion down to the specific class of conjunctive predicates and how optimisation of predicates enhances query time. In Section 3, the product function is presented as a mathematical model to describe the product of atomic predicates, an operation also referred to as concatenation. Concatenation achieves literal minimisation as an alternative to factorization where there are no common atomic predicates. Concatenation in this paper to propose the concatenated predicate model. In Section 4, the results of this study are demonstrated using mathematical induction and other proofs. The proofs are discussed relative to the expected behavior of the concatenated predicate model. Finally, Section 5 concludes the paper and makes suggestions for future work.
II. RELATED WORK
A predicate is that part of the query that filters records based on certain conditions. The properties of a predicate are multifarious and their study has exposed opportunities for optimising them, given that optimising them ultimately optimises database query time. Techniques for optimising queries are dependent on the query type.
a) Conjunctive Queries
Conjunctive queries represent one of the query languages used to retrieve data from relational databases among other database models. Conjunctive queries correspond to the non-recursive Datalog rules . In recursive datalog rules, conjunctive queries are of the form,
where is the relation name of the underlying database. is the output relation, and where each argument is a list of variables, where is the arity of the corresponding relation .
Conjunctive queries consist strictly of conjunctive predicates and they are the most widely used database queries in practice. It is against the background that optimising them makes a whole lot of sense . The wide use of conjunctive queries are observable in not only their ubiquitous use in decision support systems based on relational databases but in other areas such as Description Language queries used to query knowledge representation (KR) systems, ontology-based queries and query answering frameworks in general . Optimising a conjunctive query simply means optimising the conjunctive predicate component.
Heimel et al. [22] defined conjunctive predicates mathematically as
where are atomic predicates joined by the AND relational operators and i=1,2,..,m are predicate terms (predicate literals, Boolean variables or atomic predicates) making up the conjunctive predicate. Sargable conjunctive predicates were defined by Yu X et al.[23] as conjunctive predicates of the form,
where each component is an atomic predicate of the attribute value pair (attribute op value) with op being one of the comparison operators .
Practically speaking, conjunctive predicates are identified in the filter component of the project-select-join queries in the relational algebra, and in the where-clause of SQL queries having the general form SELECT... FROM... WHERE... where the where-clause is a predicate clause. Predicates are the conditions based on which database queries filter tuples in a relation or group of related relations. In its basic form, a query predicate is an atomic conditional expression also referred to as an atomic predicate. Several atomic predicates can be combined using logical operators to make up complex predicates [24] and the number of atomic predicates in a complex predicate is the boolean factor [9]. An atomic predicate has a boolean factor of 1. Boolean factors are notable because every tuple returned by a query must satisfy every boolean factor. A complex predicate made up of atomic predicates joined strictly using the AND logical operator is referred to as a conjunctive predicate. If all the atomic predicates in a complex predicate consist strictly of the equality operator, the complex predicate is referred to as a conjunctive equality predicate. Assuming the logical operator in the complex predicate is the OR logical operator then the resulting predicate will be a disjunctive predicate [25]. If the relational operator is the equality operator, then the complex predicate is a conjunctive equality predicate. If the conjunctive equality predicate is sargable, then it referred to as a sargable conjunctive equality predicate This paper is a study on how predicates of the class of sargable conjunctive equality predicates can be optimised.
b) Query Optimisation
Big data is resource-intensive and hence requires that both storage and query time are optimised for effective resource utilization. Resource optimisation, be it hardware or otherwise has been discussed within the larger context of solutions that we can never have enough of . As a matter of fact the optimisation problem domain is one we are not yet done with . Optimizing a number of running processes is considered an optimisation strategy though via software. Optimising query time by software (algorithms) is traditionally a function of the query optimizer, which is internal to the DBMS . The algorithms associated with the query optimiser manipulate a query plan in its internal structure to choose an optimal plan for implementing a query. Query optimization gained research attention when the advantages of the relational data model in terms of user productivity and data independence became widely recognized in response to Codd's original ideas about the concept of relational databases [28]. Following this development, researchers began to ask questions about whether or not an automatic system can choose as efficient an algorithm for processing a complex query as a trained programmer would. System R, an experimental system was then constructed at the San Jose IBM Research Laboratory to demonstrate that a relational database system can incorporate the high performance and complete function, including automatic query optimisation required for everyday production use [9,29].
Query optimization has also been associated with modifying the structure of relations. In this regard, indexing can be said to be a pioneering effort at optimising query time from the dimension of database structure . In processing a query that has a predicate, the attributes in the predicate are examined to find out if an index has been defined for any of the attributes, a concept referred to as index availability. The availability of an index makes searching relations faster compared to a full scan which is the search option used in the absence of an index. On the other hand, an index scan is used for the search if an index is available. The implementation of a full scan uses sequential search while an index scan is implemented using binary search. It is established in algorithmic theory that sequential search is of and binary search is making it obvious that an index scan is faster thereby enhancing query time.
Queries are also faster when relations are normalized. Partitioning relations also achieve good results. Optimising query operators, especially SELECTION and JOIN operators equally enhance query time. Incidentally, research into the optimisation of query operators has focused on joins and their ordering to the near neglect of research into the optimization of selection predicates . Query optimisation is an open ended research question and hence it has been the object of research efforts over the years .
c) Predicate Optimisation
Query optimisation research efforts over the years in the specific area of predicate optimization have resulted in several optimization techniques notable among which are Predicate Pushdown [37], LDL approach [38,39], Predicate Move-around [12], Predicate Migration [40], By-Pass Predicate Processing [25], Optimising User-defined functions using Pruning Strategies [41,42]. Prominent among this technique is factorisation, a technique used to minimise the number of atomic predicates or terms in a complex predicate. Kemper et al. [43] and Chaudhuri et al.[24] used factorization to minimise atomic predicates in queries. The objective of factorization is to represent a Boolean function in a logically equivalent factored form having a minimum number of literals [44]. The concept of minimizing atomic predicates (predicate literals) in a Boolean expression means that such expressions can be made simpler by reducing the terms in them. Predicate literals are found in the design of VSLI [45], compilers [46], and database query predicates [43,24] and minimization techniques of various types have been applied in each of these application areas thereby optimising the expressions involved. Factorisation is however only possible where the predicate expression has common atomic predicates.
Muralikrishna and DeWitt [47] established that the number of times a relation in a query is scanned is equal to the number of terms in which attributes of the relation are involved. This means that minimising the number of terms equally minimises the number of scans for each relation. Scanning constitutes a fundamental operation in query processing and thus a reduction in the number of scans done by a query equally reduces query time. Chaudhuri et al. [24] showed that factorization can be used to minimize predicate terms in scenarios where there are common atomic predicate factors. In this work, the sargable conjunctive equality predicates have been exposed as incidences of predicates where there are no common atomic predicate factors implying that factorization is inapplicable as a predicate minimisation technique. Sargable conjunctive equality predicates do not have common Boolean factors because an atomic predicate appearing more than once in a sargable conjunctive equality predicate duplicates such an atomic predicate. The duplicate atomic predicate is redundant and the result of such is unsatisfiable and evaluating them would lead to incorrect results . This motivates the study of the nature of optimisation problems inherent in sargable conjunctive equality predicates. The experiments performed exposed interesting insights as to why existing predicate optimisation techniques, particularly factorization are inapplicable.
d) Nature of Optimisation Problem Posed by Sargable conjunctive equality predicates
To optimise sargable conjunctive equality predicates, there is need to understand the nature of optimisation problem posed by them. Series of experiments were conducted using a simulated data of students scores in an examination to expose what happens in terms of query time when the number of atomic predicates in a sargable conjunctive equality predicate is varied in a query. The experiments performed assumed that a number of students took an examination in the Department of Physics of a hypothetical University. The examination results are captured in a database relation, named studentscores. A schema is defined for the relation as studentscores(sno, studentID, level, courseCode, semesterID, sessionID, status, score) where the attributes are described as follows: sno (serial number); studentID (unique identifier for student); courseCode (semester course code); semesterID (identifier for semester); sessionID (identifier for session); status (semester course status) and score (an attribute for students score in the examination). Five instances of this schema are shown in Table 1.
| Sno. | StudentID | Level | CourseCode | SemesterID | SessionID | Status | Score |
| 1 | SCN890178254 | 400 | PHY412 | 2016/2017 | C | 94 | |
| 2 | SCN907524101 | 400 | PHY412 | 2016/2017 | C | 65 | |
| 3 | SCN901782548 | 400 | PHY412 | 2016/2017 | C | 76 | |
| 4 | SCN898888254 | 400 | PHY412 | 2016/2017 | C | 35 | |
| 5 | SCN895428266 | 400 | PHY412 | 2016/2017 | C | 58 |
The instances of the relational schema generated in Table 1 are five but the assumption is that as many students as there wrote the examination in the physics course (PHY412). The level is 400 (a course taken at the fourth year of study except when taken as a carry over). SessionID and semesterID are 2016/2017 and 1ST respectively. The semester course is a core course hence it has the code "C" for the status. A core course in this context is a course that is compulsory for all the students doing the same course of study or programme. Elective courses on the other hand are not compulsory. They are offered by students as a matter of choice.
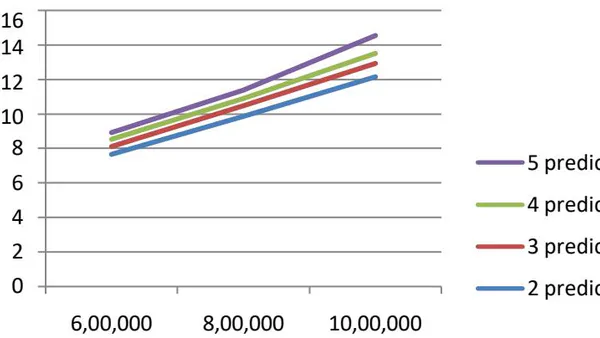
The experiments conducted involved sargable conjunctive equality predicates and it involved varying the number of atomic predicates from two to five. Five atomic predicates are realistic enough to test the behavior of a complex predicate . For each sargable conjunctive equality predicate, the number of schema instances was varied from 600,000 to 1,000,000. A data set of 1,000,000 records was assumed to be asymptotic (big data) and sufficient based on the use of the same number of records in a similar database experiment . For a sargable conjunctive equality predicate to select an instance, the atomic conditions in the conjunct must all be true for the instance. For this reason, it is common in experiments testing conjunctive equality predicates to have record instances with repeated values . The predicate attributes in the experimental data are grouped in terms of the number of predicates in the sargable conjunctive equality predicate and presented in Table 2.
| Number of predicate attributes | Predicate attributes | Sargable conjunctive equality predicates |
| 2 | courseCode, semesterID | courseCode="PHY412" and semesterID='1st' |
| 3 | level, coursecode, semesterID | Level="400" and courseCode="PHY412" and semesterID='1st' |
| 4 | courseCode,semesterID, sessionID, status | courseCode="PHY" and semesterID='1st' and sessionID="2015/2016" and status="C" |
| 5 | level,courseCode, semesterID, sessionID, status | Level="400" and courseCode="PHY" and semesterID='1st' and sessionID="2015/2016" and status="C" |
| Number of records (n) | Query time in microseconds according to number of predicates | |||
| 2 predicates | 3 predicates | 4 predicates | 5 predicates | |
| 600,000 | 7.653684139 | 8.102646112 | 8.527706862 | 8.91692996 |
| 800,000 | 9.84117198 | 10.45632792 | 10.88422108 | 11.36055684 |
| 1,000,000 | 12.14951396 | 12.91807389 | 13.49754906 | 14.54573202 |
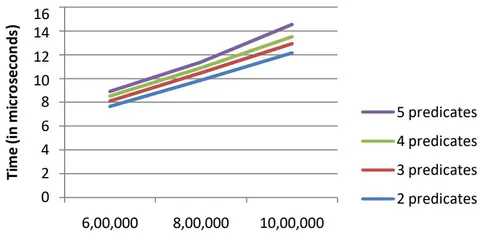
In the DBMS architecture shown in Figure 1, a query is a component of the DBMS that works in conjunction with the query optimiser to ensure queries run optimally. The query times obtained in Figure 2 includes every internal optimisation done by optimiser as well as any restructuring that can be done to the database such as indexing, partitioning, normalization and the introduction of primary keys. This scenario was earlier modeled in equation 1 as:
The point in this paper is that the query can be optimised even before it is submitted to the optimiser. A typical case in point is the use of subqueries (nested queries also referred to as queries in predicates) in place of joins in scenarios where subqueries and joins are equivalent queries. An example is where the join retrieves a single tuple, then it is less costly to use subqueries than joins. The equivalent query that optimises query time introduces an optimisation factor, to equation 1 to produce equation 2.
Where lies in the range . means there was no optimisation by the optimisation technique applied. The concept of optimizing sargable conjunctive predicates is rooted in theory of equivalent queries. For any sargable conjunctive predicates, there exists a corresponding sargable concatenated predicate.
On the basis of this insight from the experimental results in Figure 2, the concatenated Predicate model is formulated as consisting of a concatenated predicate and a corresponding surrogate index that is exploited by the concatenated predicate to enhance the query time of an equivalent sargable conjunctive equality predicate. The experiments are restricted to single table access and by implication, sargable conjunctive equality predicates [17]. Based on the experimental results, the methodology of this study consists of equations describing the product of terms (atomic predicates) which were subsequently used to formulate the concatenated predicate model. Theorems describing the application and optimality of the model as capable of optimising sargable conjunctive equality predicates are derived and also proved. It is hoped that the clarity of the concepts using the single table access will help in extrapolating the model to the other types of table access.
III. METHODOLOGY
The basic materials for this research were published literatures. Chaudhuri et al. [24] used the factorization technique to optimize a class of predicates that have common Boolean factors. The class of sargable conjunctive equality predicates on the other hand do not have common Boolean factors which makes factorization inapplicable to them. Motivated by this insight, this study unravelled some properties of the sargable conjunctive equality predicate which gave an insight on how this class of predicates can be optimised.
a) Mathematical Model
In describing the proposed model, mathematical models have been used extensively. Muralikrishna and DeWitt [47] referred to the product of the atomic predicates, in a join or selection clause as,
Each of the atomic predicates is referred to as a term. Assuming each atomic predicate, to be of the form, and denotes an attribute name of relation R and is a value, then the predicate defined is an equality predicate. The product of terms operation is also referred to as the concatenation of the terms [49]. Since in is of the form, , then can be decomposed to become,
is the product of attribute names which for ease of reference can be assigned a variable name, say C to get,
where and equation (3), defining an atomic predicate can be referred to as the concatenated predicate.
b) The Concatenated Predicate Model
Concatenation amounts to finding the product of terms, the result of which is a single term. Given the equality predicates of a sargable conjunctive equality predicate as terms, concatenation can be used to find the product of the equality predicates which results in a single atomic predicate. Put differently, concatenation reduces (minimises) the number of terms (atomic predicates) in a sargable conjunctive equality predicate to one irrespective of the number of terms . Concatenation in mathematics is the joining of two numbers by their numerals in contrast to arithmetic operations on numbers. Arithmetic operations such as addition, multiplication and all the others are based not only on the numerals but also on the magnitude of the numerals involved. Generalising, concatenation is an operation on the literals of an expression. If the term is a number, the literals are the numerals; the literals are alphabets or alphanumeric if the term is alphabetic or alphanumeric respectively.
Deen [50] exposed concatenation to be a very useful operation in computer programming and used it to generate surrogate keys as the product of an internal relation number (irn) and an effective key value (ekey value). The surrogate key generated is given by surrogate::= . In Oracle noSQL, the concatenation of a Major Key Path and a Minor Key Path was used to generate record keys [51]. All records sharing a Major Key Path are co-located to achieve data locality. Within a co-located collection of Major Key Paths, the full key, comprising of both the Major and
Minor Key Paths, provides fast indexed lookups. Concatenation has also been applied in the theory of languages [52].
To use concatenation as a product of atomic predicates in a sargable predicate, the following conditions must be met:
The values of the atomic predicate attributes of the predicate must be exact and this can only be guaranteed by the equality relational operator
The predicate terms must not be less than two and each of them must be an atomic predicate in the predicate to be concatenated. This condition can only be guaranteed when the AND logical operator is used to join the atomic predicates
The second condition is a necessary condition because different values defined for the same atomic predicate attribute in a conjunctive equality predicate is unsatisfiable and evaluating them would lead to incorrect results . In practical terms we cannot have A=12 and A=10 as a valid atomic predicates in a conjunctive equality predicate. The predicate attribute, A in a conjunctive equality predicate cannot have different values at the same time. Sargable conjunctive equality predicates meet the two conditions specified above hence concatenation is applicable to them as an optimisation technique. For every sargable conjunctive equality predicate, an equivalent concatenated predicate is derivable by concatenating the atomic predicates of the sargable conjunctive equality predicate.
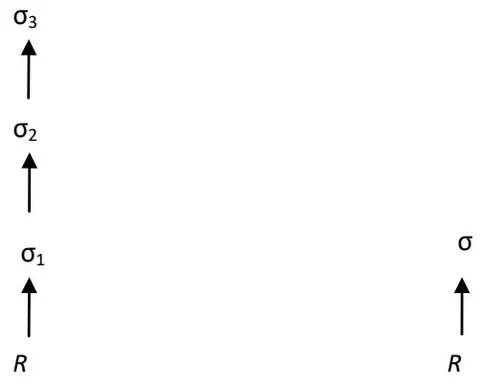
The transformation of the sargable conjunctive equality predicate to the concatenated predicate can be shown diagrammatically using a logical plan tree, the height of which depends on the number of atomic predicate operations involved in the predicate. Considering a sargable conjunctive equality predicate having three atomic predicates, , and defined on relation, R for example, the plan tree will have three predicate operations as shown in Figure 3a. The equivalent concatenated predicate, say C is a product of the atomic predicates and hence it has a single predicate operation, defined on relation R as shown in Figure 3b.
The concatenated predicate is derived from the atomic predicate attributes of the sargable conjunctive equality predicate meaning that the atomic predicate attributes must be natural attributes of the relation queried by the sargable conjunctive equality predicate.
The atomic predicate attributes are said to be sargable because they are used to search the relation. In a similar fashion, the concatenated predicate, being a product has a single attribute which it equally uses to search the relation. This also means that the concatenated predicate is also a sargable predicate. Sargable predicates search relations based on the value set of the attribute involved in the predicate. Incidentally, the attribute involved in the concatenated predicate is not a natural attribute in the relation and it has to be constructed as an artificial or surrogate attribute, call it S. The value sets of S are arrived at by concatenating the value sets of each of the natural attributes in the sargable conjunctive equality predicate as follows:
where pa is a predicate attribute of a sargable conjunctive equality predicate and , i>0 is the value set with the natural fields involved in the sargable conjunctive equality predicate. It follows from this definition that, S is the artificial attribute whose value sets is the concatenation of all for each value set of m atomic predicates in the sargable conjunctive equality predicate. This makes S one of the attributes defined for the query relation, t relative to which can be defined at the tuples of S in relation, t shown in equation (5).
The artificial attribute and its tuples referred to in equation 5 is a surrogate attribute and works very much like a user-defined index or surrogate value [30,53]. Surrogate indexes are very useful in database query optimisation [49,54,55]. The original concept of a surrogate value was to provide a unique identifier for each tuple (a kind of system primary key) that does not change irrespective of what the user chooses to do with the primary key value or the value of any of the other fields in terms of modifying them. These were called permanent surrogates. Deen [50] implemented the inpure type of surrogates in which the surrogate key changes if any of the values concatenated to generate the surrogate changes. The inpure surrogates were generated from the primary key using a hashing and a key compression algorithm, supported by an overflow mechanism. To effectively achieve this, surrogates are maintained using the following operations. When a tuple is inserted, a surrogate must be generated and the surrogate directory updated. This operation is referred to as surrogate generation. When a tuple is deleted, the surrogate directory must be updated, releasing the surrogate for possible re-use. This operation is referred to as surrogate release. Given the value of the attributes that make up the surrogate key value, the system should be able to find the surrogate. This operation is referred to as surrogate access. Given a surrogate, it should be possible to find the stored tuple. This operation is referred to as storage access and in this role, the surrogate serves the purpose of a data structure that can be exploited by predicates to locate records.
Diagrammatically, when the surrogate index is exploited by a concatenated predicate, tuples of the associated relation that match the predicate condition are fetched. The tuples defined in Equation (5) that are fetched by the concatenated predicate are depicted in Figure 4.
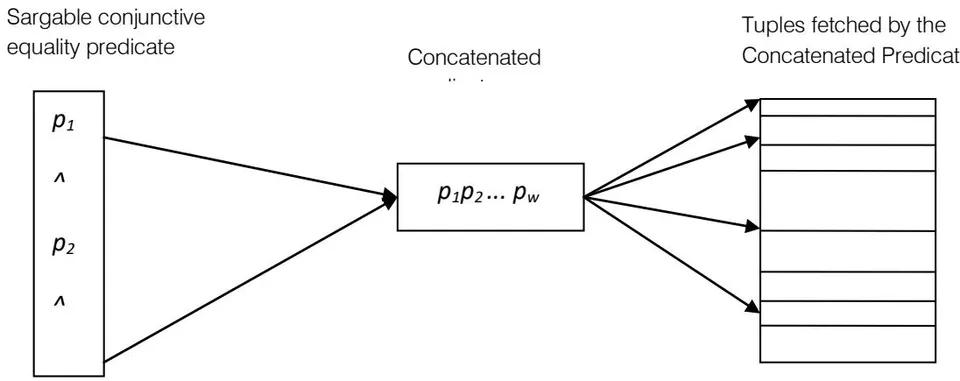
Figure 4 is a diagrammatic representation of how the concatenated predicate is evaluated. Let be the concatenated predicate on the query table, t, then equation (6) models the evaluation of . A tuple, is returned from the query table by when the concatenated predicate is evaluated and the result is true.
IV. RESULTS AND DISCUSSION
Resulting from the experiments performed in order to gain an understanding of the nature of optimisation problem posed by sargable conjunctive equality predicates, the Concatenated Predicate model was formulated as consisting of a concatenated predicate and a corresponding surrogate index that is exploited by the concatenated predicate to enhance the query time of an equivalent sargable conjunctive equality predicate. This result is proved using formal methods for their correctness. The correctness of this result is discussed as a theoretical proof of the concatenated predicate model.
a) Proof of Existence of the Concatenated Predicate
Lemma 1: The equality condition in a sargable conjunctive equality predicate guarantees uniqueness of its atomic predicates because a conjunct of two different filters on the same attribute is unsatisfiable [22].
Theorem 1: For every sargable conjunctive equality predicate, there exists a product of its atomic conditions called the concatenated predicate
Proof: Theorem 1 follows from the work of [47] and [22]. Muralikrishna and DeWitt [47] and Heimel et al. [22] defined a conjunctive predicate as, AND , AND... AND and as being equivalent to a product of its atomic predicate terms expressed as , where each in both the product term and the conjunctive term is strictly a Boolean expression and each in the sargable conjunctive equality predicate is an equality predicate.
b) Proof of Equivalence
Lemma 2: Two query predicates (conditions) are equivalent if they return the same records from a compatible database [11].
Theorem 2: The product of atomic predicates (concatenation operation) is a bijective function on the set of concatenated predicates from the set of sargable conjunctive equality predicates thereby defining their equivalence
Proof: Let , where A is the set of sargable conjunctive equality predicates and , where B is the set of the concatenated predicates and D is a compatible database containing the surrogate field derived from the concatenation of the natural fields of D in the sargable conjunctive equality predicates. Let f represent the operation that concatenates the atomic conditions in a to get b. Then if and only if, f is a bijective function. To be bijective, f must be onto as well as one-to-one:
f is onto because each concatenated predicate, b in B is in the image of f. That is,
f is one-to-one because for a concatenated predicate, there is at most one such that . That is,
where a ` is the inverse of a going by the concatenation operation implied by f.
Given that (3.10) and (3.11) holds, we conclude that is a bijective function on the set of concatenated equality predicates to the set of conjunctive predicates because f is both one-to-one and onto.
A B and hence they return the same number of records for a compatible database
c) Proof of Optimisation
The generic optimisation model of a relational database query is described in terms of a relational algebra expression. The relational algebra corresponding to a query describes a set of operators whose number can be determined and their cost estimated. Based on either number of operators or estimated cost, two queries can be compared to ascertain that one optimizes the other. A relational algebra expression e optimises another relational algebra, e if the following conditions are satisfied (1) e is equivalent to e given a compatible database (2) the query time of e is less than that of e. e is optimal if a relational algebra expression that optimises e` does not exist.
Theorem 3: A predicate, is optimal relative to the conjunctive equality predicate, , if (1) is equivalent to the conjunctive equality predicate, (2) has fewer occurrences of equality predicates than , and (3) there exists no other predicate, that is equivalent to and has fewer occurrences of equality predicate than .
Proof:
The proof consists of a lemma and a proof by induction on , the number of equality atomic conditions in the predicate, . The lemma establishes the equivalence of C to , while the proof by induction establishes the optimality of compared to C.
Lemma: Two query predicates (conditions) are said to be equivalent if they each return the same records from a compatible database [11].
Induction hypothesis: Consider the query execution tree in Figure 3 and let number of atomic predicates. Each atomic predicate in corresponds to a predicate operator . In all circumstances, for since is a product of the terms of . Being a product, the number of terms in is and so for .
Initial Induction Step: The height of the tree corresponding to C = number of atomic predicates in , where m is the number of atomic predicates in C. Assuming as the initial induction step, m is defined in subsequent induction steps as m - i, where i is the subsequent induction step, defined as 1, 2,..., m. That is, in each subsequent induction step, we decrease the number of atomic predicates, m, by one at a time.
When i=5, then m-i=5-5=0 implying When m approaches 0, approaches 0
This means that the number of operators, decreases in proportion to the number of atomic predicates, m. Mathematically,
The query does not work and is undefined for when , . The query processes the least number of selection operators and hence does the least amount of work when , . Recall that for predicate . This means that is optimal since any other reduction of the atomic predicates in will result in a predicate that has and by the lemma, the equivalence of since is proved
The proof assumes that the cost of execution of a predicate is directly proportional to the number of atomic predicates that makes it up. This was proved by previous experiments.
One of two equivalent predicates optimizes the other if the query time associated with the optimising predicate is lesser and both predicates are equivalent given a compatible database.
Proof: The relational algebra of the concatenate predicate and the sargable conjunctive equality predicate are made up of the same operator, the selection operation. The proof that the concatenate predicate, has fewer occurrences of operators than CP the conjunctive predicate and hence optimizes the sargable conjunctive equality predicate is as follows
Let the compatible database be R and the relational algebra corresponding to the sargable conjunctive equality predicate be e and the algebra of the concatenated predicate be e'. Then e = \sigma_{P1\and\P2,\and...} and and where the number of atomic predicates in e, . Given that e' is a product, it follows that . Given and , we can assume the minimum value of m = 2 for e resulting in e = \sigma_{P1\AND\P2}(R). The relational algebra of e and e' consist of the selection operation, whose implementation uses either the sequential search (table scan) or the binary search (indexed scan). Since both e and e' are made up of the same operation, it is convenient to assume that table scan has been used to implement them in the following algorithmic procedure.
The algorithmic steps corresponding to are:
Apply the selection operator to get the intermediate relation,
Apply the selection operatorto get the intermediate relation,. The final result analysis:
Assume the arity of the intermediate results, and to be approximately of the uniform value, n respectively. Let the total query time of be . then . The algorithmic steps corresponding to are:
- Apply the selection operatorto get the intermediate relation,. The final result.
Analysis
Assume the arity of the intermediate results, and to be approximately of the uniform value, n respectively. Let the total query time of e be $f_{e} \cdot (n)$. then $f_{e} \cdot (n) = \text{query time of } I = n$ Clearly, $f_{e}(n) > f_{e} \cdot (n)$, meaning that the query time of e is less than that of e implying that e` optimises e. The proof of optimality follows.
d) Proof of Optimality
Theorem 4: Given two equivalent relational algebras where one optimises the other, the one that optimises is optimal if a relational algebra expression that optimises it does not exist
Proof: The proof that the concatenated predicate, C that optimizes the conjunctive equality predicate, CP is optimal is proved by induction on m, the number of predicates in both C and CP.
Induction hypothesis: Each atomic predicate in CP corresponds to a predicate operator on the logical plan tree. Assuming m to be the number of atomic predicates in CP and be the number of predicate operators on the corresponding logical plan tree, then for every additional atomic predicate, increases by 1 such that .
Induction Step: Assuming CP has a single atomic predicate, then m = 1 and . Proceeding with the induction steps, we increase the number of atomic predicates, m, by one at a time to get,
...When m approaches , approaches
This means that the number of operators, grows in proportion to the number of atomic predicates, m. Mathematically,
But C is a product, implying that the number of terms in C is m = 1 and so for every C corresponding to CP For there to exist a predicate that optimises C, the occurrence of operators in such a predicate, m, must be zero, that is m < 1. If m = 0, then will also be zero. defines a predicate that has no atomic predicate which is non-existent and hence a predicate that optimises C is non-existent. This means C having one operator has the least number of operators and hence it is optimal.
In this section, the proof of correctness of the concatenated predicate model has demonstrated. Table
3.4 shows the equations used to model the various components of the model.
| Model Component | Equation |
| Conjunctive Predicate | |
| Conjunctive Predicate as a product of terms | |
| Concatenate Predicate | |
| Surrogate Index | |
| Model Evaluation |
V. CONCLUSION AND SUGGESTION FOR FURTHER WORK
The optimization of queries where complexity is due to a large number of joins has received a lot of attention in the database literature, but the optimization of complex selection predicates involving multiple ANDs (conjunctive predicates) and ORs (disjunctive predicates) has not been widely addressed . In lieu of the dearth of research into selection predicates, the contribution to knowledge of this research effort can be said to be significant. Enhancing the query times of sargable conjunctive equality predicates is significant in the following ways:
The optimisation of the sargable conjunctive equality predicates within the context of big data minimises query time which tend to increase with big data
Sargable conjunctive equality predicates are widely used in applications involving data extraction, mining, matching and resolving data entities [56]. Enhancing these predicates directly improves the running times of applications designed to automate these operations.
Considering the very many other areas in which an improved query time can be of use, the research is of significance to software architects, software developers, the software industry and researchers.
The concatenated predicate model works very much like an index hence we can refer to it as a surrogate index. In our subsequent work, the concatenated predicate model will be experimentally validated and work on how to integrate the surrogate index into existing DBMS architecture studied.